AI Test Automation: How It Works, Uses, and ROI
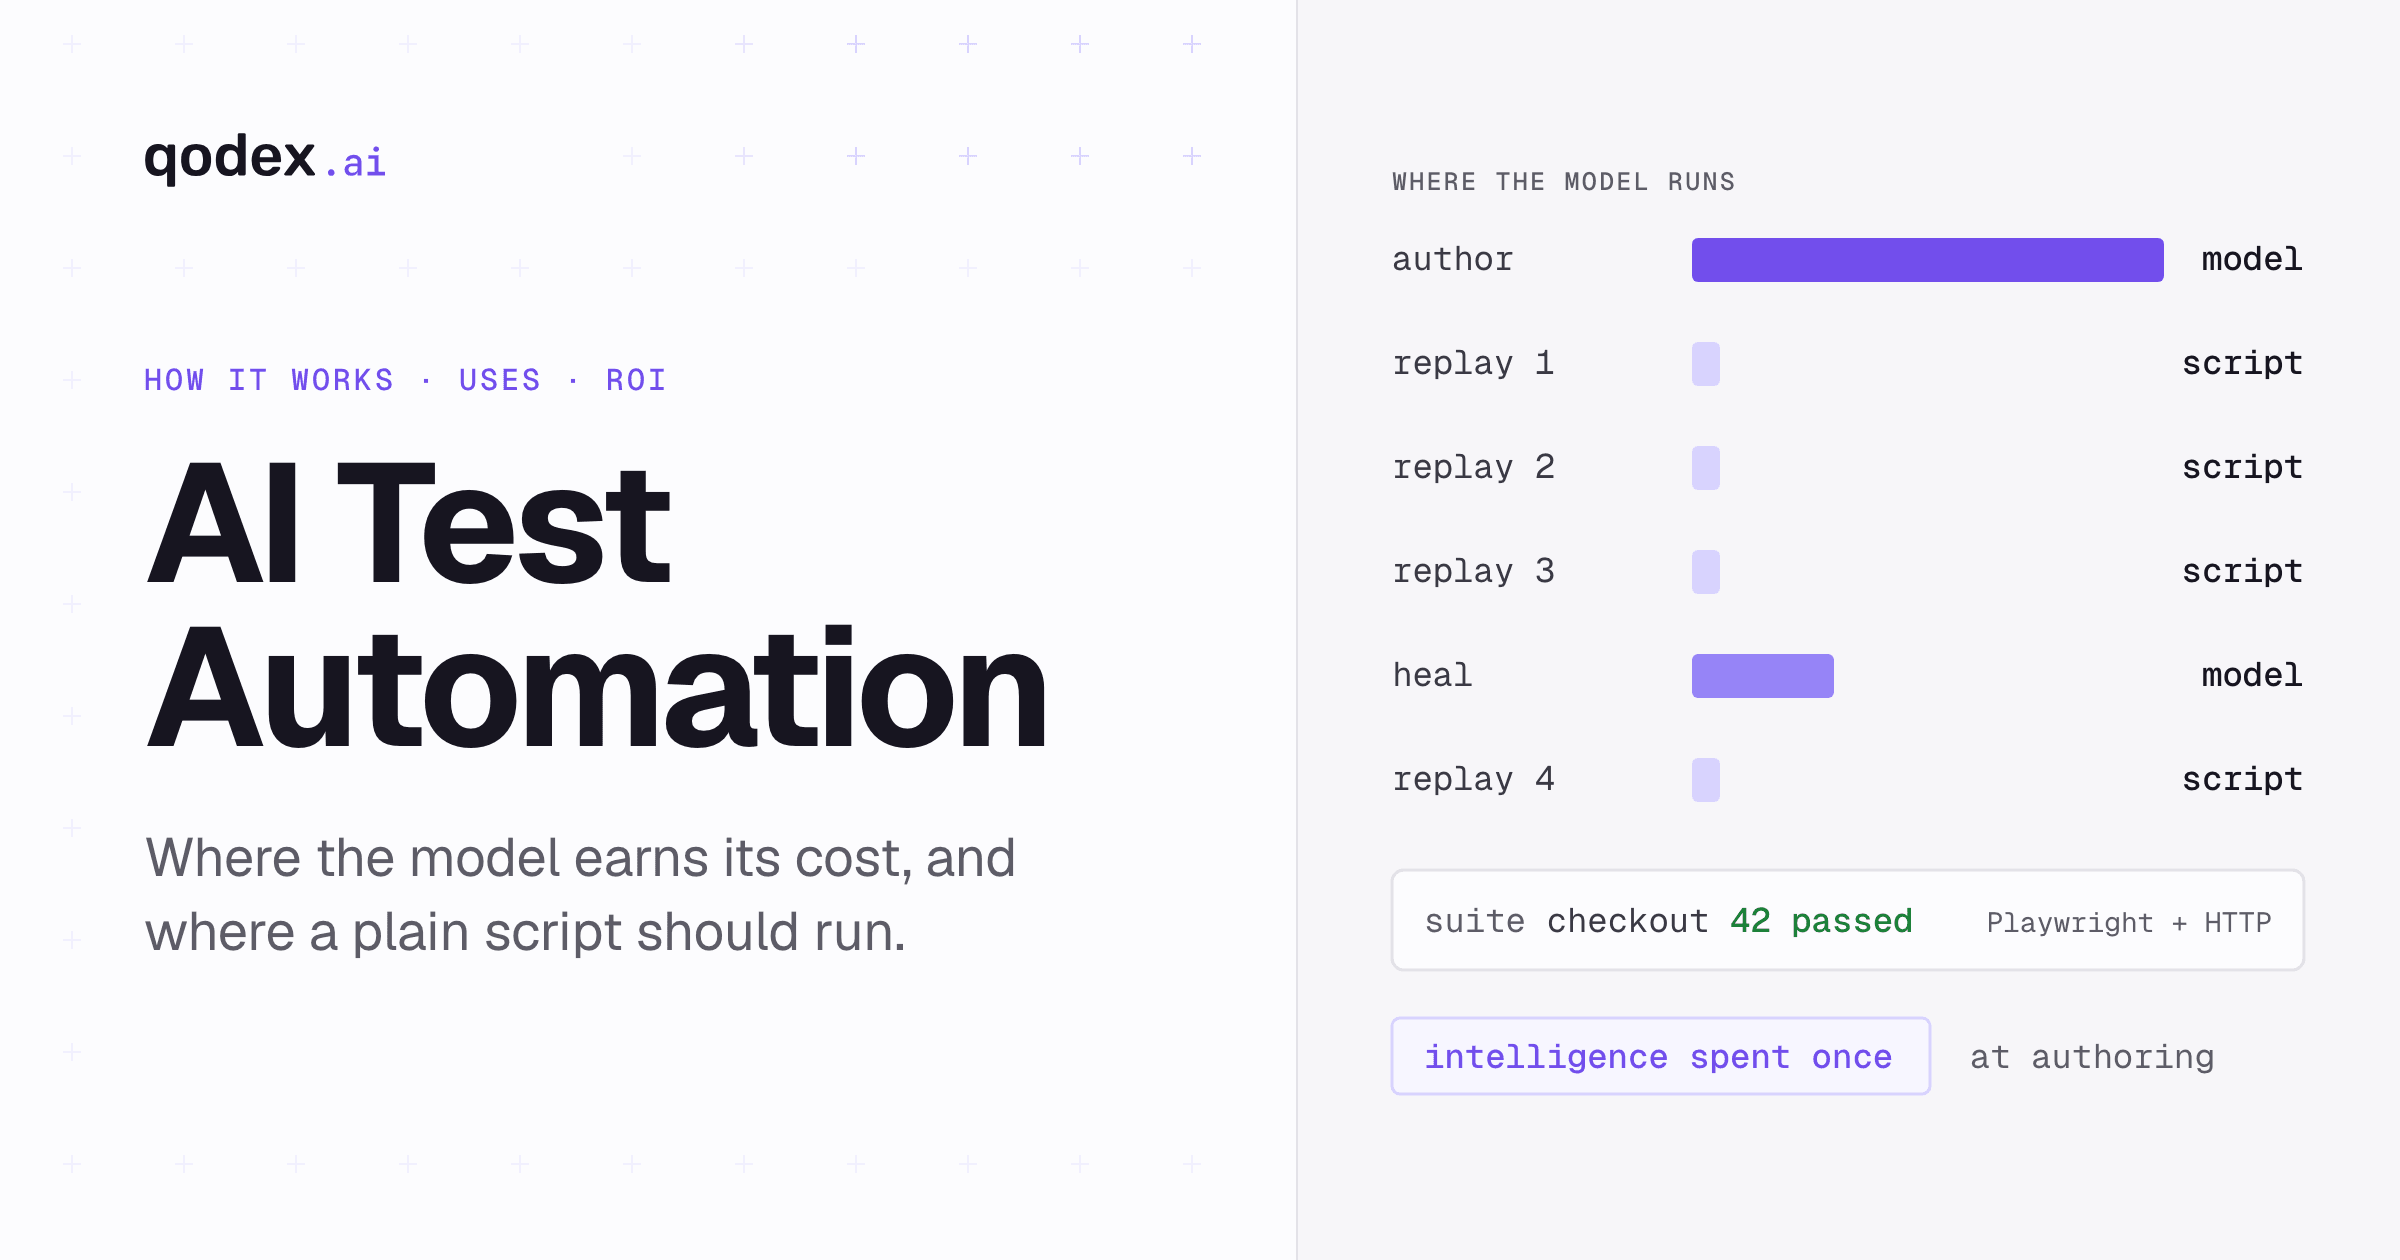
AI test automation uses machine learning, generative AI or computer vision to help create, select, run, maintain and interpret software tests. It sits on top of normal test automation rather than replacing test strategy or human judgment. The useful forms are test generation, resilient element matching, visual checks, risk-based selection and failure triage. Measure it by time saved, reliable coverage and escaped defects, not tests generated.
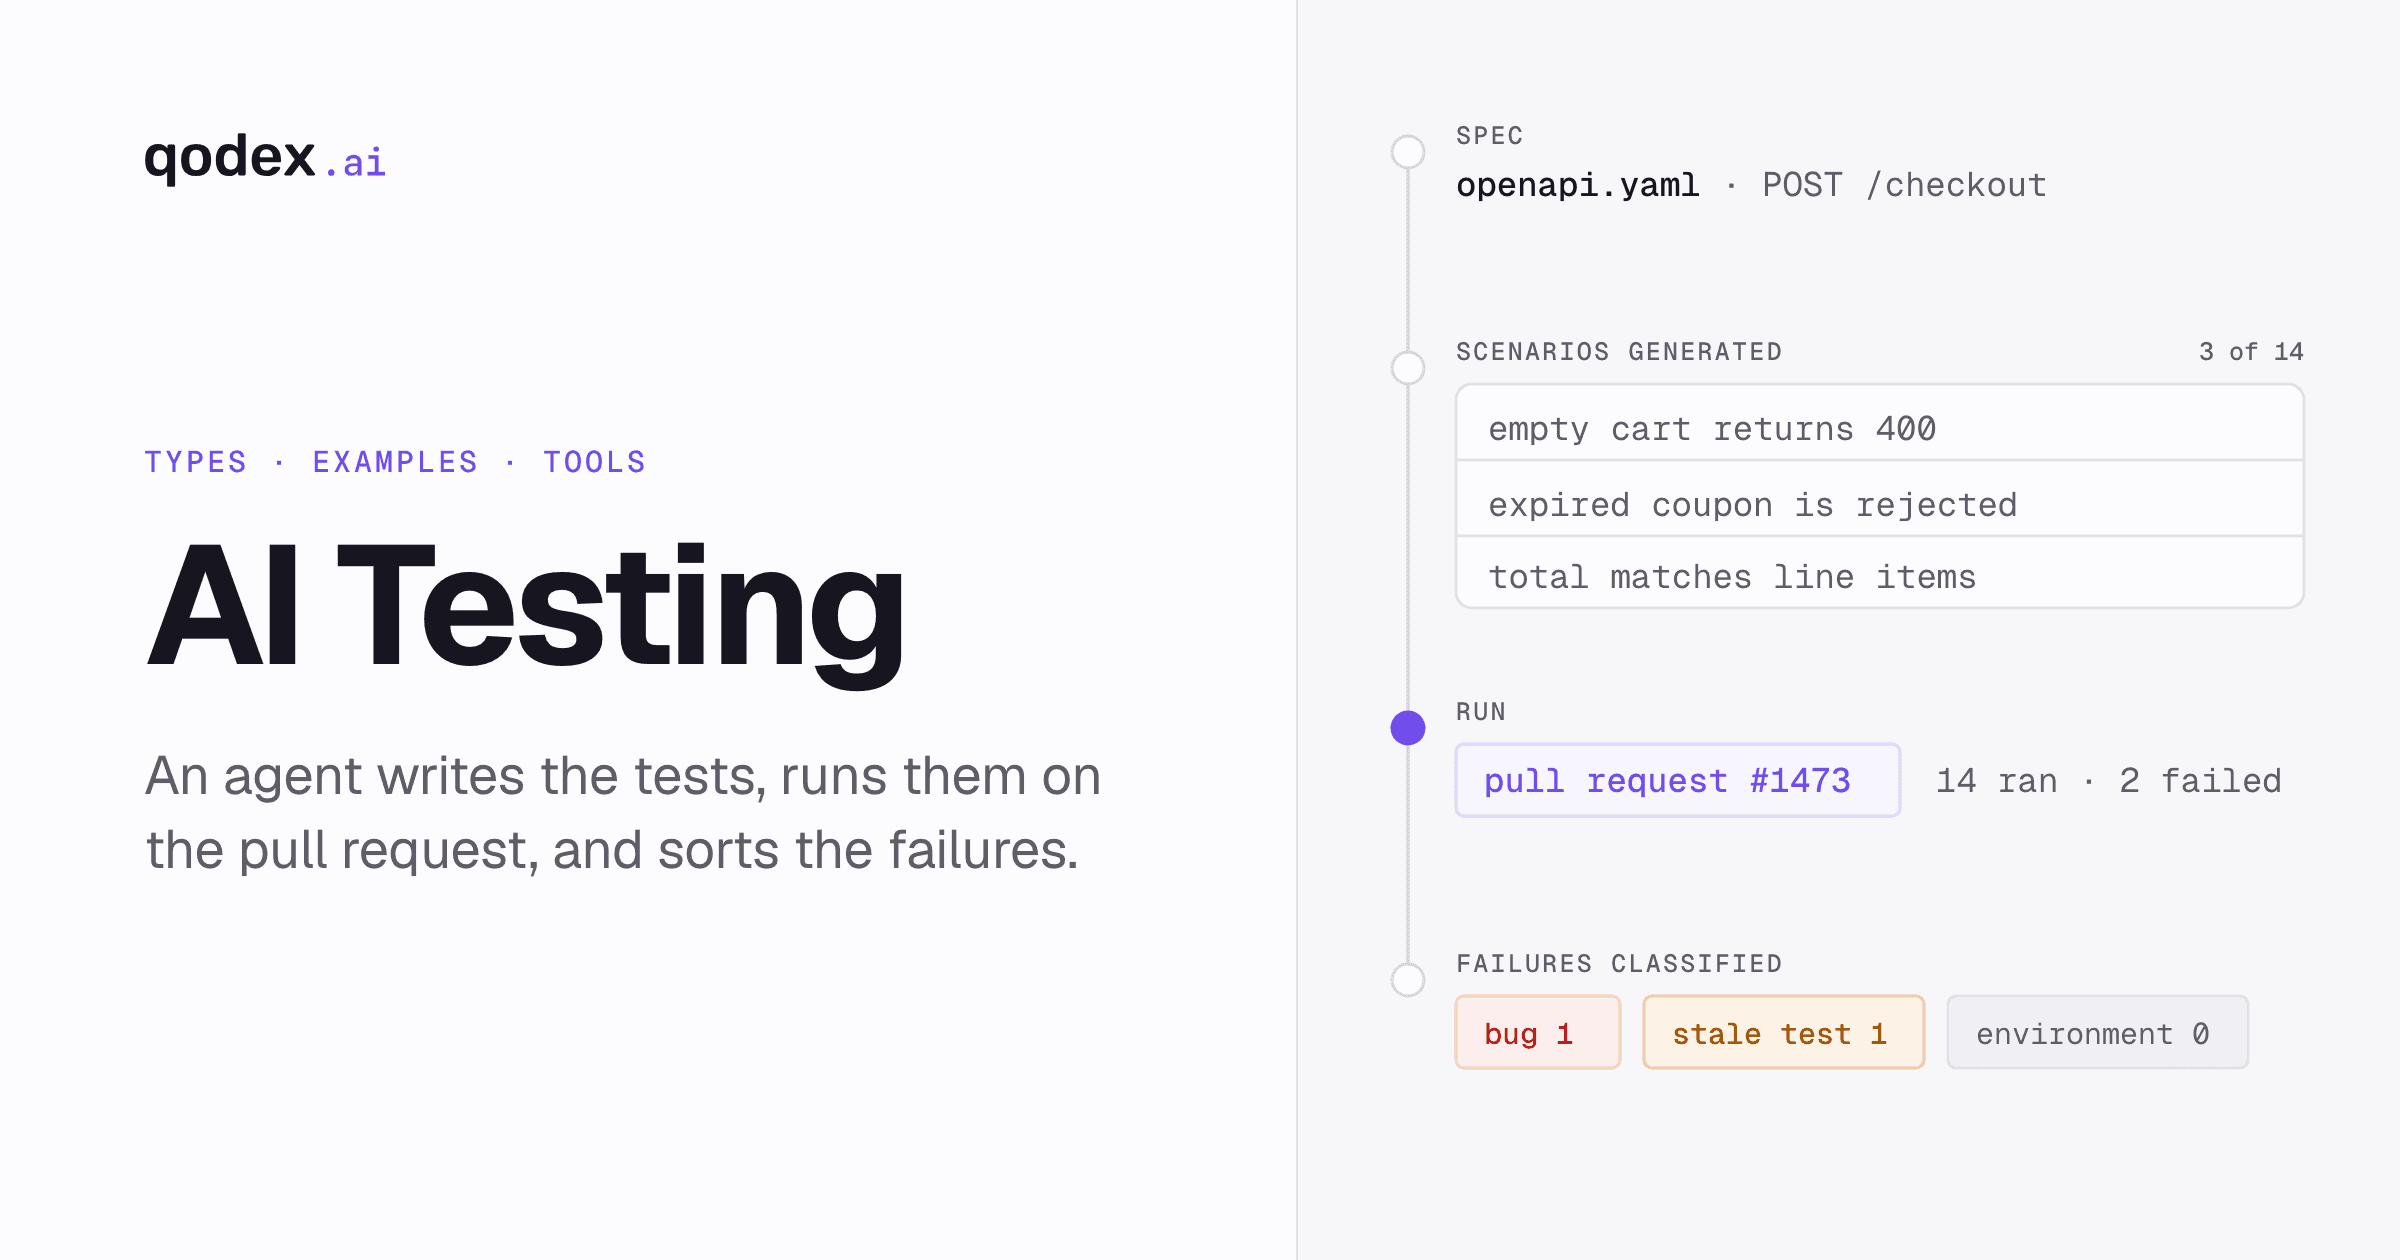
Qodex is one way to get this without building the AI layer yourself: it writes API tests from your spec and runs API, UI and security testing on every pull request and deploy. See Qodex API testing.
What AI test automation means
ISTQB defines test automation as "The conversion of test activities to automated operation". AI test automation is that same work with a model doing part of it. It adds machine learning, generative models or computer vision to one or more test activities: writing tests, choosing which ones to run, running them, keeping them working as the product changes, and reading the results. Source: ISTQB glossary, read 15 September 2026.
The label has an edge worth holding. A suite that replays saved Playwright specs across parallel browsers is fast automation, not AI. Harness keeps the two apart on one product page: the parallel execution service is infrastructure, while the plain-English assertions and the failure explanations are the model. When a vendor says AI, ask which activity the model touches and what it hands back. For the wider view of where models sit in QA work, read AI in software testing.
There is a second boundary. Using AI to test your software is not the same as testing an AI system, and ISTQB keeps separate syllabuses for the two. This page is about the first. The second is its own discipline, and ISTQB carries separate syllabuses for it: Specialist AI Testing v2.0 and Specialist Testing with Generative AI v1.0.
Two shapes exist in the market today. In the first, the model writes or repairs a test and you keep the output: a spec file, a set of steps, a list of assertions that run the same way on every future run. In the second, an agent decides at run time what to click and what counts as correct. The first is auditable and repeatable. The second reaches further, but it can answer differently on different days, which matters when the run is a merge gate.
How AI test automation works
Whatever a vendor calls its product, the AI test automation lifecycle has six stages. Sources: Harness, Ranorex and Testsigma, read 15 September 2026.
Context in. The system reads requirements, user stories, an OpenAPI specification, recorded traffic, screenshots, the existing suite, the code diff, logs and past run history. The quality of this input sets the ceiling for everything after it.
Generation. The model proposes tests, steps, data or assertions from that context. The output is either an artifact you keep in the repository or a plan an agent will carry out.
Execution. The tests run in CI, against a preview environment or on a device cloud. Execution is either deterministic, replaying saved steps, or agent-led, deciding each step as it goes.
Evidence capture. Requests, responses, screenshots, video, console output and timings are stored per run. Without this, nothing downstream can be checked by a person, and a model has nothing to reason over.
Failure classification. A model sorts failures into real defect, environment problem, changed expectation or unstable selector. It groups repeat failures across runs and suggests a cause.
Proposed maintenance. The system offers a repair for a broken test, usually a new selector or an updated expectation, and a person approves it.
The last stage is where teams get hurt. Healing that merges its own repairs with nobody reading them will quietly delete coverage: a test that stops asserting the thing that broke still turns green. Keep the approval step, and review healed tests the way you review code.
The split between the two execution styles decides where each belongs. Generated-then-saved tests fit the merge gate, because the same input is checked the same way on every run and a failure points at one change. Runtime agents fit exploratory sweeps, first-pass smoke runs on a new feature and coverage of paths nobody wrote down. Teams that run agents as a merge gate spend their week arguing about whether a red build is real.
Where AI fits in the testing lifecycle
AI does not help equally at every test level. It helps most where the input is already written down and the output can be checked.
Unit tests. A model reads a function and writes cases for it, including branches a person skips. The input is code the model can read and the output is a file you can review, which is why this is a common starting point. It is also the easiest place to fool yourself: generated unit tests often assert what the code currently does, not what it should do. Review the assertions, then make a temporary change in a scratch branch and confirm the tests go red before you revert it.
API tests. Judge a test level by two criteria: whether the input is already machine-readable, and whether you can check the output. API testing scores on both. To automate API testing with artificial intelligence, a model turns an OpenAPI specification, a Postman collection or recorded traffic into scenarios with auth, request data, contract assertions and status expectations. It then runs them in CI and triages what breaks.
UI and end-to-end tests. Element matching that survives a renamed class or a moved button removes a large part of the maintenance bill. The trade is opacity: a test that finds a different element than you meant can pass for months.
Visual checks. Computer vision compares renders and flags the differences a raw pixel diff would drown you in. Pair it with a review step, as in these visual regression testing methods.
Regression selection. Given a code diff and run history, a model ranks which tests are worth running now. Useful when a full suite takes hours. Keep a full run on a schedule, or the unranked tail rots.
Test data. Generation of realistic records, edge values and combinations, which is the slow part of data-driven testing.
Failure analysis. Grouping repeat failures, separating unstable tests from real defects and drafting a root cause from logs and diffs. This is often the first place a team feels the time come back.
The order matters as much as the list. APIs and units come first because their inputs are text a model can read and their output is a file you can review in a pull request. UI journeys come later, because judging whether a screen is correct needs the business context a model does not have. Performance and security work sits further out again: a model can draft load scenarios or fuzz an endpoint, but the pass or fail threshold is a decision your team owns.
AI test automation vs traditional automation
The honest comparison is stage by stage. Traditional automation is people writing and maintaining instructions that a runner repeats. AI automation moves some of the writing, choosing and reading onto a model, and leaves a human check in each place where a wrong answer is expensive.
| Lifecycle stage | AI job | Input | Output | Human check | Best metric | Main failure mode |
|---|---|---|---|---|---|---|
| Test design | Propose cases and edge conditions | Requirements, stories, specs, code diff | Draft case list | Does it match the real risk? | Valid defects found per suite | Plausible cases that miss the business rule |
| Authoring | Write steps and assertions | Case list, spec, recorded traffic | Saved test in the repository | Read the assertions | Authoring hours per scenario | Asserts current behavior, not correct behavior |
| Test data | Generate records and combinations | Schema, constraints, sample data | Data sets per case | Privacy and realism | Setup hours per scenario | Data that could not exist in production |
| Element matching | Locate elements after a UI change | DOM, screenshots, history | Resolved locator | Spot-check healed tests | Maintenance hours per sprint | Matches the wrong element and stays green |
| Execution | Decide or replay steps | Saved test or live plan | Run result and evidence | Rerun before believing a red | False-failure rate | A different answer on the same build |
| Failure triage | Classify and group failures | Logs, diffs, screenshots, history | Cause suggestion | Confirm before closing | Triage hours per failing run | Real defect dismissed as flaky |
| Maintenance | Propose a repair | Failing test, new UI or contract | Suggested patch | Approve it like code | Escaped defects | Silent healing that deletes coverage |
What stays deterministic is the part you keep: the committed test, its assertions and the CI gate that runs it, so the same input is checked the same way every time.
Benefits and limits
The benefits that hold up are concrete and narrow. Authoring gets faster, because a first draft of a scenario arrives without anyone writing it. Maintenance gets cheaper, because small UI and contract changes stop breaking every test at once. Triage gets faster, because failures arrive grouped with a suggested cause instead of as a wall of red rows. Measure each of those three against the hours you recorded before you started.
On AI software testing efficiency, one rule matters more than any vendor number: measure against your own baseline. Record authoring hours, maintenance hours, feedback time and escaped defects for one service before you start, then compare the same four numbers once the pilot has run long enough to produce them. Testsigma advertises large multiples for speed and maintenance on its product page. Those are vendor claims on a sales page, not independent benchmarks, and no independent benchmark for a universal productivity gain turned up in the pages reviewed for this guide.
The limits are real and they recur across the reviewed sources. Ranorex puts it plainly: "AI can't replace human testers". A model does not know your business logic, so it will not tell you that a refund should never exceed the original charge. Its decisions are hard to inspect, so a test can pass for the wrong reason. It misses edge cases and outliers that a tester who has watched real users would catch. And it invites overreliance: green builds feel like evidence, even when the assertions have stopped meaning anything. Sources: Ranorex and Testsigma, read 15 September 2026.
The work that stays human is test strategy, deciding what quality means for this product, reviewing what the model wrote, and owning the gate.
How to adopt AI test automation
TestGuild gives the best selection rule in six words: "Start with the pain, not the hype" (TestGuild, read 15 September 2026). Name the bottleneck first. Flaky tests eating CI time, maintenance after every UI change, and regression runs that cannot finish inside a sprint are three different problems with three different answers.
Baseline the bottleneck. For one service, write down authoring hours per scenario, maintenance hours per sprint, time from commit to test feedback, and escaped defects per quarter. Without these four numbers, nothing you do next can be evaluated.
Pilot on real software. Use a service you ship, not a demo app.
Verify every output. Read the generated assertions. In a scratch branch, make a temporary change that should break the behavior, confirm the tests go red, then revert it. A suite that never fails is not coverage.
Integrate, then gate. Run the suite on every pull request, with the evidence attached to the failure. Gate merges on it only once the false-failure rate is low enough that people stop clicking rerun.
Expand on evidence. Add the next test level when the four baseline numbers have moved on the first one.
Score tools on the same scorecard: which activity the model touches, whether you keep the output, whether it runs in your CI, what evidence it stores, and how a repair gets approved. For the current field, see the best AI QA tools, and for the wider move away from hand-scripted suites, intelligent test automation strategies.
Metrics and ROI
Measure the inputs you control first: authoring hours, maintenance hours, triage hours, run cost, tool cost, implementation time, training time, false-failure rate, valid defects found and escaped defects. These are the inputs closest to the change you made. A fuller list sits in test automation metrics.
Treat delivery metrics as downstream outcomes, never as proof. DORA's five software delivery metrics are change lead time, deployment frequency, failed deployment recovery time, change fail rate and rework rate. DORA is explicit that context matters and that the metrics suit one application or service at a time, rather than comparisons between unlike teams. Source: DORA, read 15 September 2026.
What is ROI in test automation? It is the net gain divided by what you spent, as a percentage: ROI = (benefit minus cost) / cost x 100. State the period and include every cost, including the hours your own team spent. Simple ROI disregards time, so the same percentage over one year and over three years are not the same result. Source: Corporate Finance Institute, read 15 September 2026.
Here is a worked example for one year. Every number below is an assumption chosen to show the arithmetic. It is not a benchmark and not a claim about what your team will get.
| Assumption | Value |
|---|---|
| Sprints per year | 24 |
| Manual regression before | 80 hours per sprint |
| Manual regression after | 24 hours per sprint |
| Loaded labor cost | $60 per hour |
| Escaped defects avoided | 4 per year at $5,000 each |
| Tool cost | $24,000 per year |
| Setup effort | 160 hours, once |
| Upkeep | 8 hours per sprint |
The labor benefit is 56 hours saved per sprint across 24 sprints at $60 an hour, which is $80,640. The defect benefit is $20,000. Total benefit is $100,640. Costs are $24,000 for the tool, $9,600 for setup and $11,520 for upkeep, which is $45,120. Net benefit is $55,520, so ROI is 55,520 / 45,120 x 100 = 123.0% in year one.
Run the sensitivity before you present it. Saved hours and avoided defects are the two variables illustrated here; labor rate, tool cost, setup and upkeep move the answer as well. Without the defect savings, the same costs need 31.3 saved hours per sprint to break even. With them, 17.4 hours per sprint is enough. If your regression suite does not take 31 hours of manual work per sprint, the case has to come from defects escaping less often, not from hours. The same arithmetic works for one test level on its own. For the ROI of API test automation, put only your API regression hours, the share of tool cost you attribute to API runs and the defects your API suite catches into the same formula.
Some numbers look like progress and are not. Tests generated is the clearest example: a model writes assertions faster than anyone can review them, and a suite nobody trusts costs more to run than it returns. Coverage percentage has the same problem when the new lines are covered by tests that assert nothing. If you report a count, report it next to the false-failure rate and the valid defects those tests actually caught.
Two warnings on attribution. Your quarter contained other changes: a hiring round, a rewrite, a quieter release calendar. Hold one service as the unit of measurement and keep the baseline you recorded, or the number you report is just the story you wanted. And never borrow another company's percentage, including the one above. The point of a transparent model is that a stakeholder can change your assumptions and watch the answer move.
Frequently Asked Questions
What is AI test automation?
AI test automation adds machine learning, generative models or computer vision to one or more test activities: generating tests, selecting which to run, running them, maintaining them or analyzing the results. It sits on top of ordinary test automation. It does not make every automated test an AI test.
How is AI test automation different from traditional automation?
Traditional automation repeats instructions a person wrote. AI automation moves part of the writing, choosing and reading onto a model. The runner, the assertions and the CI gate stay the same. The difference shows up in who drafts the test, who repairs it after a UI change, and who sorts the failures.
Can AI generate unit tests?
Yes. The catch with AI unit testing is that generated tests tend to assert what the code does today, which locks in the bug you already have. Read the assertions. Then, in a scratch branch, make a temporary change that should break the behavior, confirm the tests fail, and revert it.
How can AI automate API testing?
Point it at an OpenAPI specification, a Postman collection or recorded traffic. The model turns endpoints into scenarios with auth, request data, contract assertions and expected statuses, runs them in CI against a preview environment, and classifies what broke. The inputs are machine-readable, so the output is easy to verify.
What is self-healing test automation?
When a test fails because an element moved or a class was renamed, the system proposes a new locator or expectation for a person to approve. It cuts maintenance. It is safe only with a human approval step, because silent healing can remove the assertion that was catching the defect.
Can AI replace QA engineers?
No. Ranorex states it plainly: "AI can't replace human testers". Models do not know your business rules, they miss edge cases, and their decisions are hard to audit. Test strategy, reviewing generated tests and owning the release gate stay human work.
What metrics should measure AI test automation?
Direct inputs first: authoring hours, maintenance hours, triage hours, false-failure rate, valid defects found and escaped defects, each against a baseline you recorded before adoption. Delivery metrics such as change lead time and change fail rate are downstream outcomes, useful as a trend and weak as proof.
What is ROI in test automation, with an example?
ROI = (benefit minus cost) / cost x 100. In the worked model above, a benefit of $100,640 against a cost of $45,120 gives a net of $55,520 and 123.0% in year one. Every input there is a stated assumption, so replace them with your own hours and rates.
How do you implement an AI test automation lifecycle?
Pick one bottleneck and baseline four numbers for one service. Pilot on software you actually ship, and verify the generated output with a temporary change in a scratch branch. Wire the suite into pull requests with evidence attached, and only then gate merges. Move to the next test level when the baseline numbers have moved.
Is testing with AI the same as testing an AI system?
No. Using AI to test software means a model helps generate, run, maintain or triage your tests. Testing an AI system means evaluating a model's own behavior, including accuracy, bias, prompt handling and non-determinism. ISTQB keeps separate syllabuses for the two disciplines: Specialist AI Testing v2.0 and Specialist Testing with Generative AI v1.0, both listed on its current glossary record for test automation.
Summary
AI test automation is a model doing part of the test work: drafting, selecting, matching elements, triaging and proposing repairs, with a person approving what lands. It helps most on APIs and units, and least where the business rules live. Judge it against your own baseline, keep every repair under review, and build the ROI case from assumptions a stakeholder can change and recalculate.