10 Best Generative AI Testing Tools in 2026
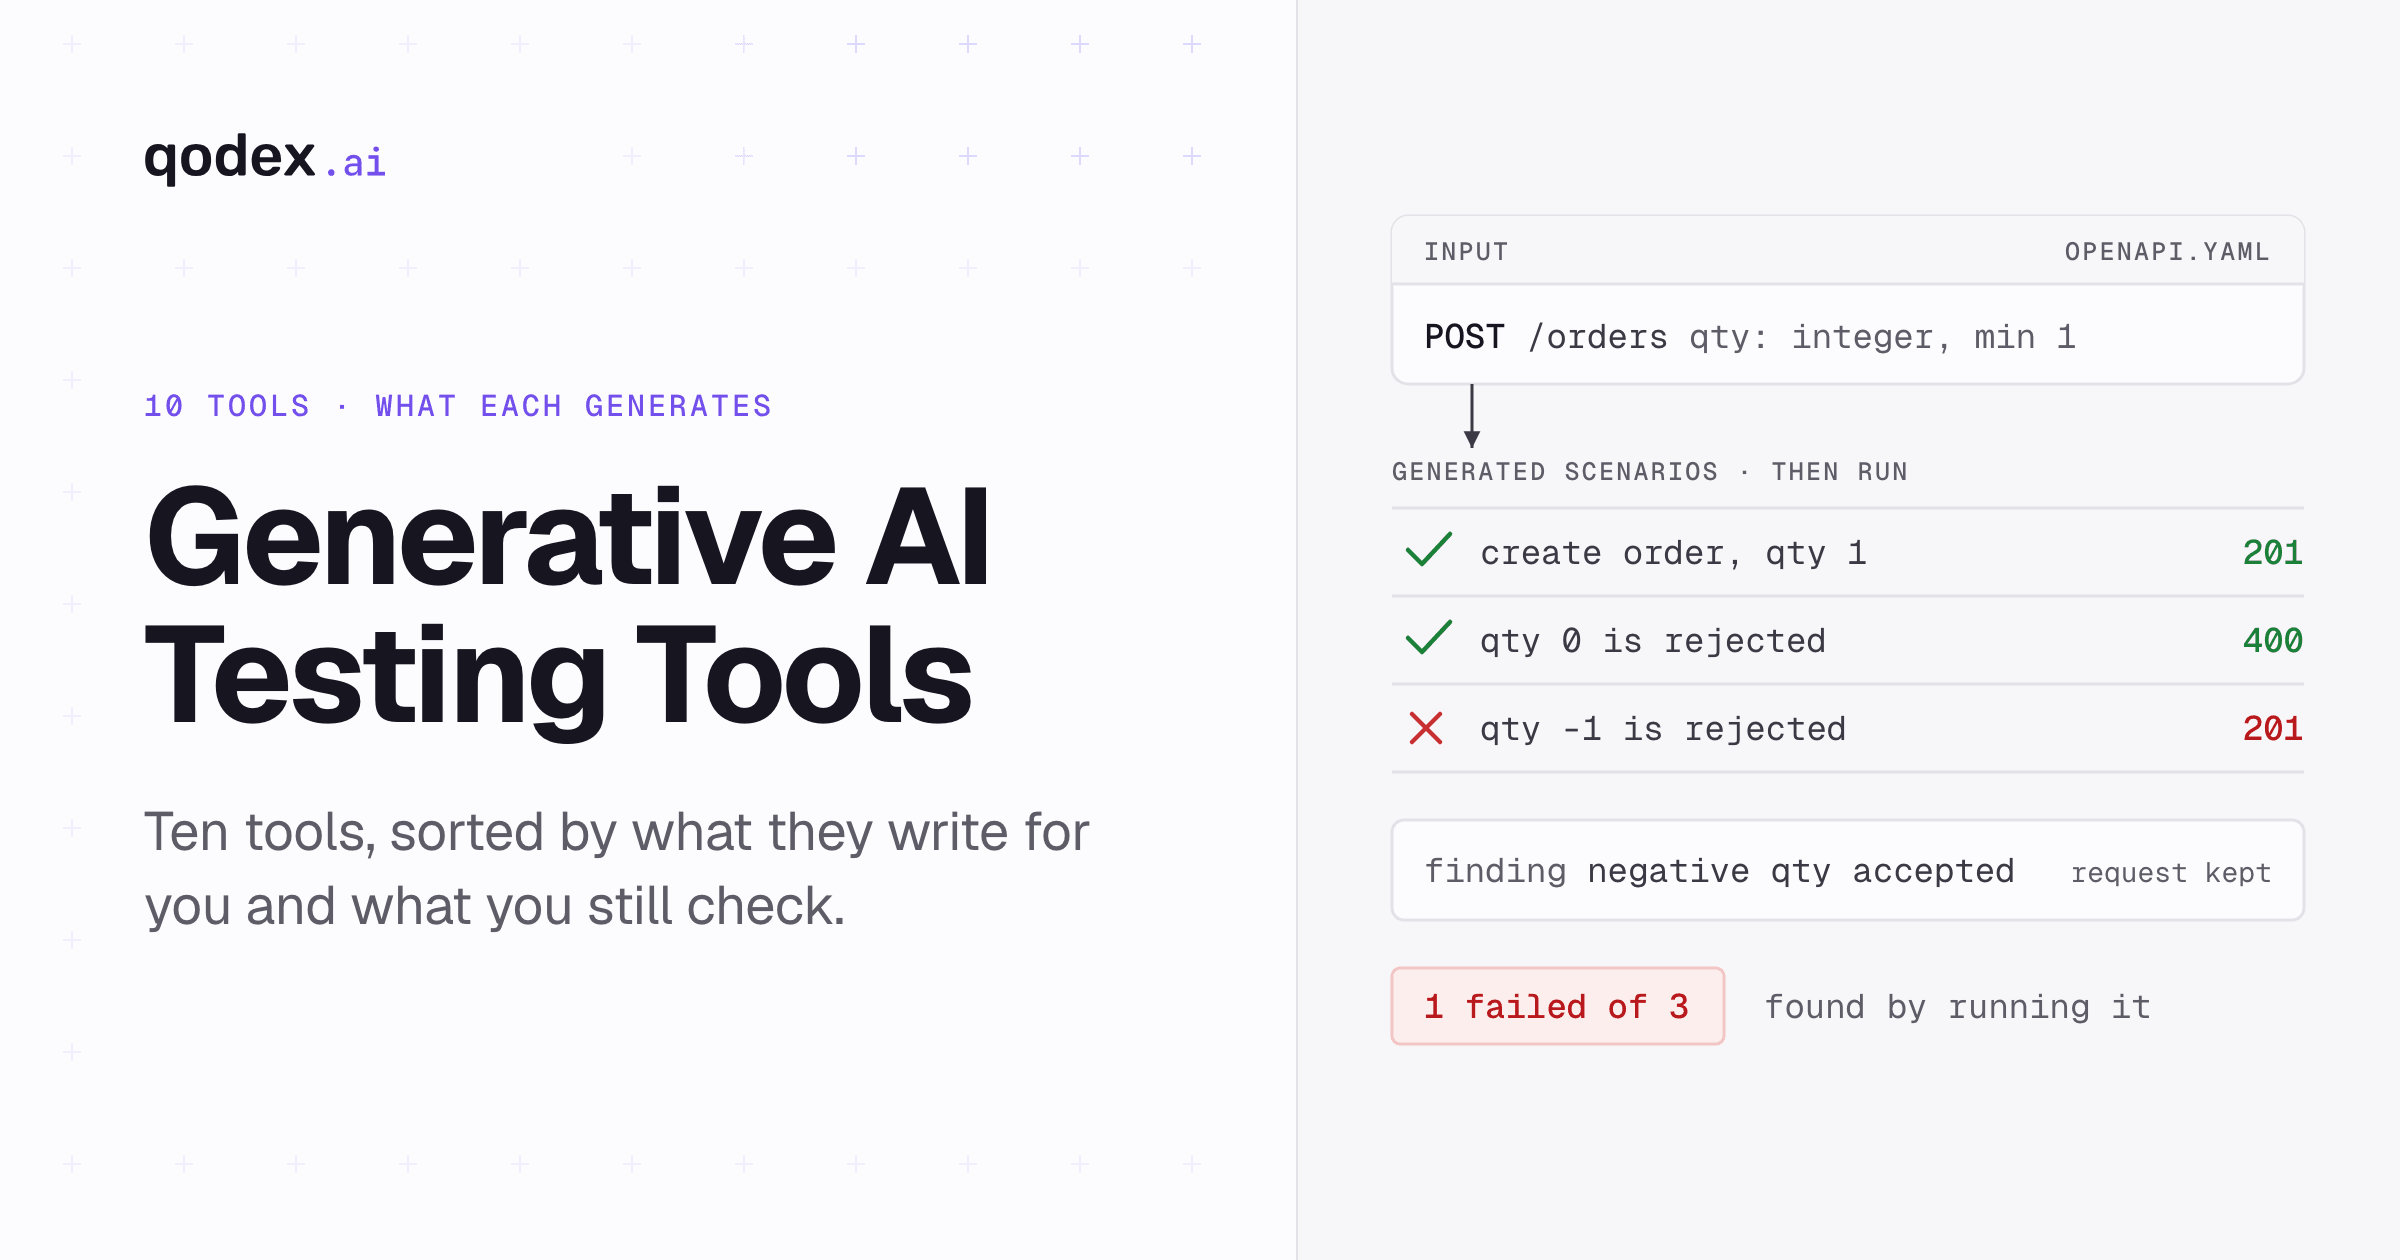
The leading generative AI tools for software testing in 2026 are Qodex, mabl, testRigor, Testsigma Copilot, TestMu AI KaneAI, ACCELQ Autopilot, Momentic, Diffblue Testing Agent, Applitools Autonomous, and Promptfoo. They cover different jobs, from turning plain English into runnable UI and API tests to generating unit tests and evaluating LLM applications. Choose by test layer, generated artifact, workflow, evidence, and pricing.
What counts as a generative AI testing tool
NIST defines generative AI as a model that emulates its input data to "generate derived synthetic content". Read 15 September 2026. Here that content must be a testing artifact: a scenario, a case, a script, a data set, an assertion or an evaluation. A tool that only ranks, compares or repairs existing tests is not listed here.
The phrase has a second meaning: tools that test generative systems. Promptfoo is the one labelled entry for that.
For predictive selection, visual analysis and self-healing, see AI testing software and QA tools. For a wider platform comparison, see best AI QA tools.
Generative AI testing tools compared
Read the table by the artifact you want generated. A unit-test generator and an end to end scenario generator rarely substitute, so match the layer first.
| Tool | Generated artifact | Best test layer | Runs the test? | Paid start and unit | Free plan or trial | Best for |
|---|---|---|---|---|---|---|
| Qodex | API and UI scenarios, saved as Playwright you own | API and UI end to end | Yes, against every pull request preview | From $1,299 per project per month | Individual at $0, 25 scenarios and 100 runs a month | Generating and running API and UI scenarios from a spec or a sentence |
| mabl | Web, mobile, and API tests | Web, mobile, API | Yes | Custom, quoted per organization | 14-day free trial | One agentic platform across several layers |
| testRigor | End to end tests written in plain English | Web and mobile end to end | Yes | Not published for Private or Enterprise | Free public plan, plus a 14-day Private trial | People who are not engineers writing end to end tests |
| Testsigma Copilot | AI-generated test cases | Not specified on the pricing page | Yes | Custom for Pro and Enterprise | Not published | Teams already on Testsigma who want case generation |
| TestMu AI KaneAI | Cross-layer tests from natural language and files | Web and mobile end to end | Yes | $19 per agent per month for 2,000 credits | No free KaneAI plan | Teams that want per-agent pricing with visible credit limits |
| ACCELQ Autopilot | Automation logic and test data from everyday English | Front end, back end, API, middleware | Yes | Not published for Autopilot | Manual-testing tier is free for life | Enterprises standardizing on one codeless platform |
| Momentic | Plain-English web and mobile tests | Web and mobile end to end | Yes | $125 per month for 10,000 credits | Free with 2,000 credits a month | Small teams that want metered credit pricing |
| Diffblue Testing Agent | Java and Python unit tests | Unit | Yes, it verifies its own output | From $1,500 for 5,000 net-new covered lines | Not checked | Raising unit coverage on a large Java or Python codebase |
| Applitools Autonomous | Tests from scans, recordings, and plain English | Web functional and visual | Yes | Not published for the generative tier | Free trial | Teams whose first problem is visual regression |
| Promptfoo | LLM evaluations and red-team probes | LLM application | Yes | Custom for Enterprise and on-premises | Community edition, open source, 10,000 probes a month | Testing a generative feature rather than a UI |
"Paid start and unit" is a published list price, or "not published" where the vendor shows none. None of it is a total cost: credits, agents, sessions and covered lines are not comparable units. "Runs the test?" marks the tools that also execute what they generate.
Every capability below is the vendor's own description, read 15 September 2026, unless another source is named.
The 10 generative AI testing tools
1. Qodex
Qodex turns something you already have, or a single sentence, into scenarios that run. Its API page puts it plainly: "Import a spec, a Postman collection, a spreadsheet, or one sentence. Runnable scenarios, run against every PR preview, replayed for $0." The UI side follows the same shape: "Describe the flow in a sentence. Qodex drives the real app, brings back a screenshot of what broke, and saves the run as Playwright you own."

Generated artifact. API and UI scenarios. UI runs are saved as Playwright you own.
Input. An OpenAPI spec, a Postman collection, a spreadsheet, or one sentence.
Runs the test? Yes, against every pull request preview.
Price. Individual is $0 per project per month, free for every developer. Startup is from $1,299 per project per month, a starting price scoped to your team and usage.
Free plan. Individual, with API and UI scenario runs against your app, core OWASP-aligned security probes, and up to 25 test scenarios and 100 test runs per month.
Main limit. Those 25 scenarios and 100 runs a month set the ceiling on a free evaluation.
Details of the API side are on the Qodex API testing page.
2. mabl
mabl describes itself as "the agentic testing platform that gives you coverage that builds itself, runs itself, and recovers itself". Read 15 September 2026. In practice that means test generation across web, mobile, and API, with agentic maintenance keeping tests alive as the interface moves.
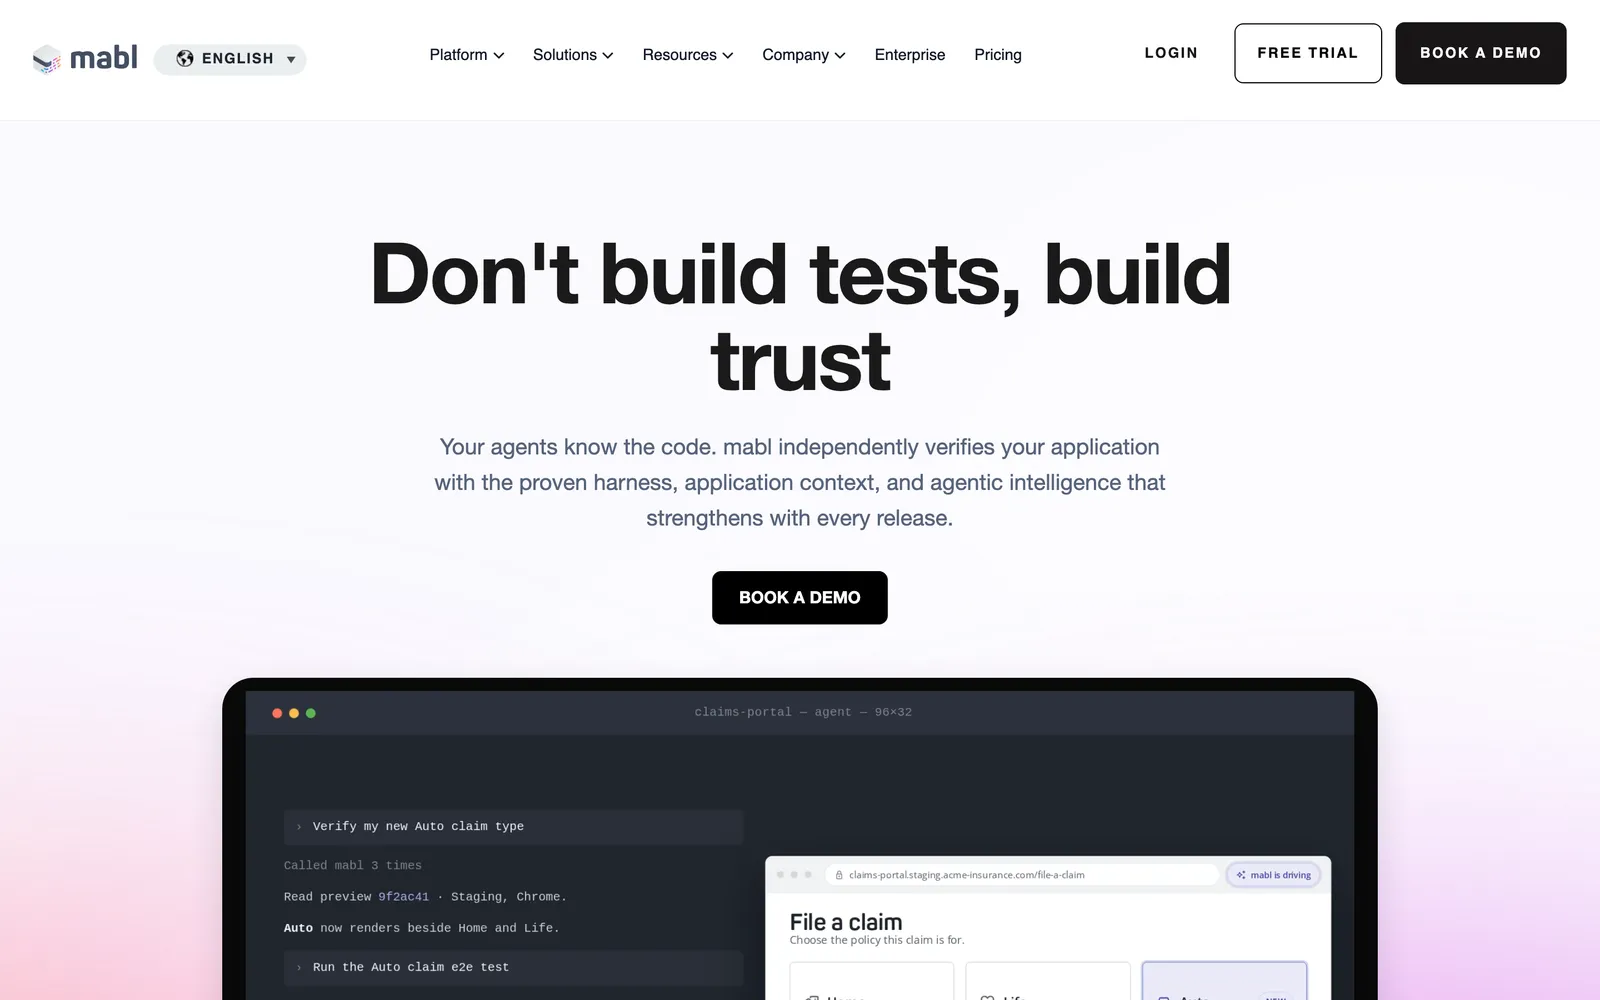
Generated artifact. Web, mobile, and API tests, plus proposed repairs.
Input. Not specified on the pricing page read for this list. The generated surfaces are web, mobile and API.
Runs the test? Yes, in mabl's cloud.
Price. Custom, quoted per organization. Cloud test runs start from 500 credits a month, shared across browser, mobile UI, and API runs.
Free plan or trial. A 14-day free trial.
Main limit. There is no published price, so the cost of your usage is unknown until you talk to sales, and credits are the unit that decides it.
The pricing page answers the trial question directly: "mabl offers a 14-day free trial to allow users to experience our platform firsthand," with the period described as a chance to explore all features before committing. Read 16 September 2026. If the credit model or the quote does not suit you, see mabl alternatives.
3. testRigor
testRigor generates end to end tests from plain English, and the tests stay in plain English afterwards. The vendor's own framing is that its parser reads plain English and executes those specifications directly, so the test file is the specification rather than a layer over Selenium code. Read 15 September 2026. That is the strongest argument for it: a product manager can read the suite.
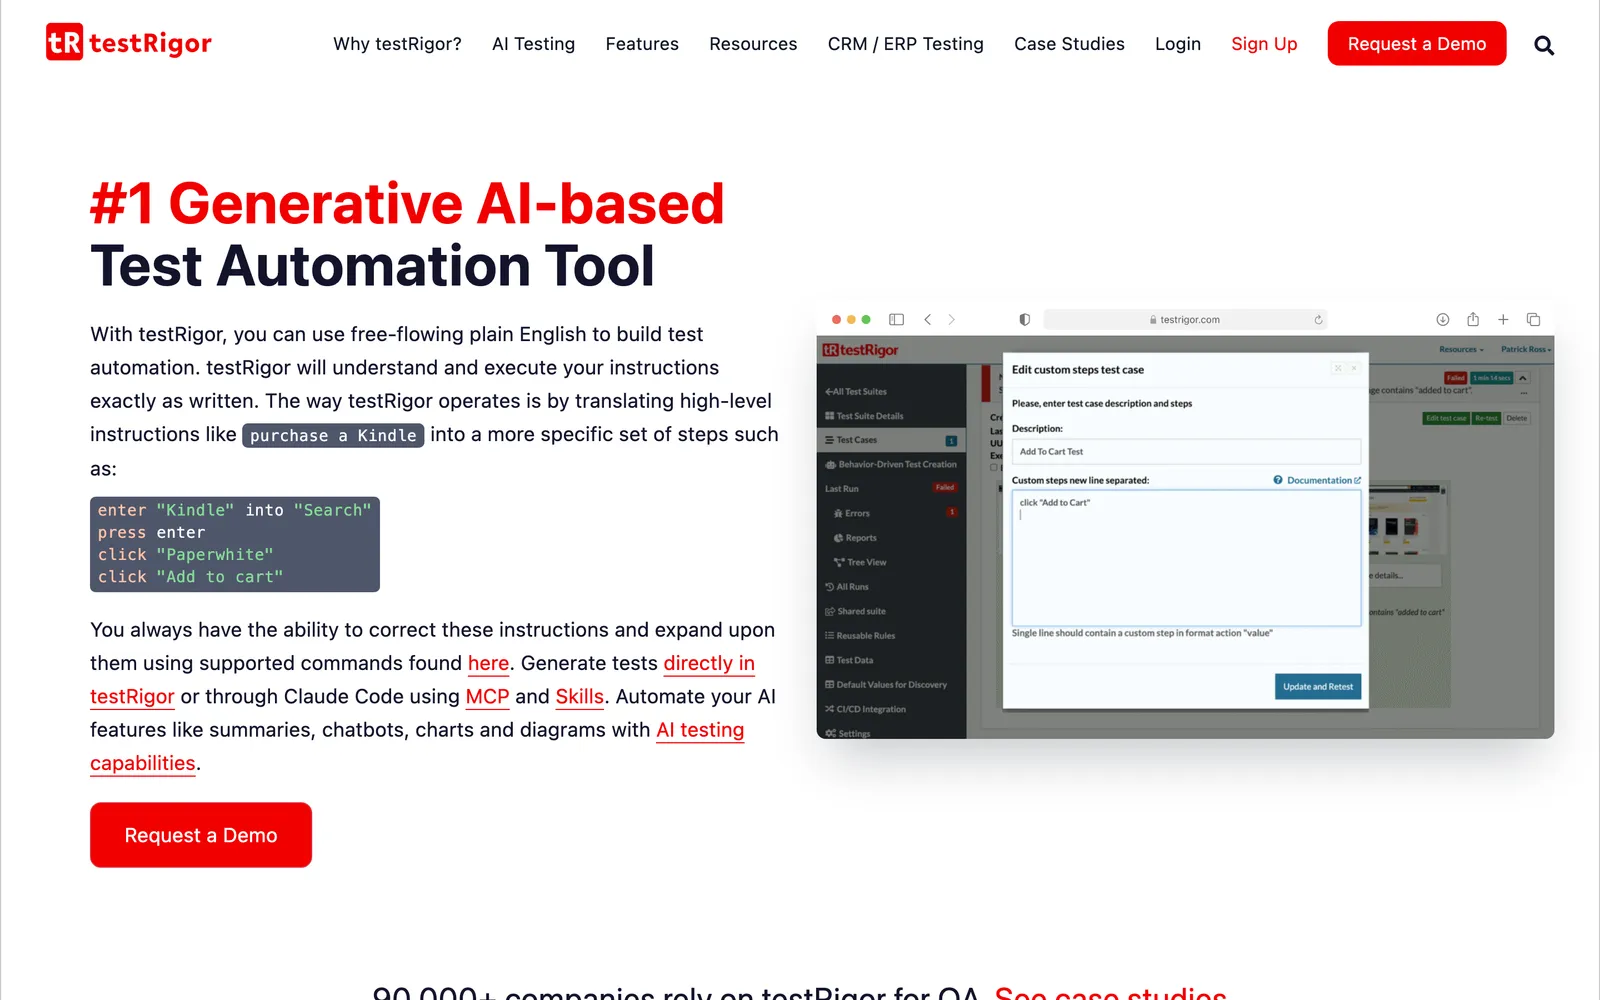
Generated artifact. Executable end to end tests expressed in plain English.
Input. Free-form English describing what a human would do.
Runs the test? Yes.
Price. Not published for the Private or Enterprise plans at the read date.
Free plan or trial. TestRail reports a free public plan whose results are public, plus a 14-day trial of the Private plan. Read 15 September 2026.
Main limit. Plain English is readable but not precise. Ambiguous steps produce tests that pass for the wrong reason.
For other plain-English options, see testRigor alternatives.
4. Testsigma Copilot
Testsigma positions Copilot as an AI testing companion inside its low-code platform, with AI-powered test case generation listed as a plan feature. Read 15 September 2026. Note what the pricing page also says: autonomous testing is marked "Upcoming", so the agentic end of the product is not something you can buy and run today.
Generated artifact. AI-powered test case generation, listed as a plan feature.
Input. Not specified on the pricing page read for this list.
Runs the test? Yes. Its plans list unlimited automated testing minutes, parallel execution, 800+ browser and OS combinations and 2,000+ real mobile devices. Read 16 September 2026.
Price. Custom for Pro and Enterprise. The page sends you to a quote rather than a number.
Free plan or trial. Not published on the pricing page at the read date.
Main limit. Copilot generates inside Testsigma. If you are not already committed to the platform, you are buying a platform to get a generator.
The same feature list shows what comes with the generator: public, private or on-premises cloud deployment, SAML 2.0 single sign-on, geo-based testing, a private grid, IP whitelisting and more than forty integrations. Read 16 September 2026. If the platform is the sticking point, compare Testsigma alternatives.
5. TestMu AI KaneAI
KaneAI, from TestMu AI and previously part of LambdaTest, turns natural language and uploaded files into tests across layers, and its own page describes an agent that writes, runs and proves them. It is the one tool here with a fully public price ladder, which makes budgeting straightforward.

Generated artifact. Web and mobile tests, authored from natural language or a requirements file.
Input. Natural language and uploaded files.
Runs the test? Yes.
Price. $19, $99, and $199 per agent per month for 2,000, 12,000, and 25,000 credits. Paid annually the same tiers are about $17, $89, and $179. Read 15 September 2026.
Free plan or trial. No free KaneAI plan.
Main limit. Billing is per active agent as well as per credit, so a team that adds authors adds licences, not just usage.
TestMu AI also ships Kane CLI, which automates end to end flows on a local browser from natural language and is being offered with 10,000 free credits for a month. Read 16 September 2026. It lets you inspect what the generator produces before buying agent seats.
6. ACCELQ Autopilot
ACCELQ builds Autopilot around Q-GPT, a logic builder it describes as "Everyday English for Automation". It takes plain-English business rules and generates automation logic and realistic test data across the front end, the back end, APIs and middleware. Read 15 September 2026.

Generated artifact. Automation logic and test data.
Input. Business rules written in everyday English.
Runs the test? Yes. Its plans list cloud or on-premises execution, and an ACCELQ Cloud Lab that runs tests on the vendor's execution labs. Read 16 September 2026.
Price. No public price is shown for Autopilot.
Free plan or trial. A manual-testing tier is listed as free for life.
Main limit. The generative features sit inside a full platform, so evaluating Autopilot means evaluating ACCELQ, and the price for that is a conversation.
That platform is broad. ACCELQ lists codeless record and instant playback across web, desktop, cloud ERP applications, mainframe and files, plus zero-setup codeless automation for real-device native and browser apps. Read 16 September 2026.
7. Momentic
Momentic writes, runs, updates, and triages plain-English tests for web and mobile. Its pricing page is unusually specific about what consumes credits, which is rare enough in this category to be worth reading before you commit to anything else.
Generated artifact. Plain-English web and mobile tests, plus failure classification and triage.
Input. A description of the flow in plain English.
Runs the test? Yes.
Price. Pay as you go is $125 a month for 10,000 credits, with overage at $0.01875 per credit. Read 15 September 2026.
Free plan or trial. Free, with 2,000 credits a month, about 200 typical runs.
Main limit. Everything is metered, and the expensive operations are the AI ones. The pricing page prices each one separately: 300 credits for an AI test selection from a code diff, and hosted mobile emulator time at 8 credits a minute on Android and 15 on iOS. Its pricing page lists failure classification at 100 credits per run classified and triage at 500 credits per run triaged, read 16 September 2026, so heavy diagnosis is what moves the bill.
For similar agentic options, see Momentic alternatives.
8. Diffblue Testing Agent
Diffblue is the outlier on this list because it works at the unit layer and sells on verified output. It generates Java and Python unit tests and puts them through its own verification framework, so what reaches you is meant to compile, pass, and add coverage rather than to be reviewed into shape.

Generated artifact. Java and Python unit tests.
Input. Your source code. Java 8, 11, 17, 21, and 25 and Python 3.9 and above are supported.
Runs the test? Yes, as part of verifying what it wrote.
Price. From $1,500 for 5,000 net-new covered lines, an effective $0.30 per line. Read 15 September 2026.
Free plan or trial. Not checked for this list.
Main limit. Unit tests only, and only two languages. Generated unit tests also tend to encode current behavior, which locks in a bug as readily as a feature.
9. Applitools Autonomous
Applitools came from visual testing and extended into generation: Autonomous creates tests from site scans, recordings, and plain English, and covers functional, visual, API, and PDF checks. Its own page says Autonomous "lets QA and manual testers describe tests in plain English, then executes them with a Deterministic Language Model", read 16 September 2026.
Generated artifact. Functional and visual tests built from a scan, a recording, or a description.
Input. The application, a recorded session, or plain English.
Runs the test? Yes.
Price. The published Starter tier is $667 a month paid annually, and what it lists is visual validation with Visual AI, not generative functional testing. The generative tier is not published. Read 15 September 2026.
Free plan or trial. The Starter tier offers a free trial, read 16 September 2026.
Main limit. The published number does not buy the feature this page is about, so the real price needs a quote.
Also on the page. Autonomous groups its features as create, execute and analyze: a codeless recorder, an NLP builder and a website crawler, then cross-browser execution, test orchestration and self-healing, then root-cause analysis and automated maintenance. Read 16 September 2026.
10. Promptfoo
Promptfoo is here for the other meaning of the phrase. It tests generative systems instead of generating tests for conventional software: evaluations for LLM output, vulnerability scanning and red-team probes. If your product now has a chat feature, this is the layer nothing else on this list covers.

Generated artifact. LLM evaluations and adversarial red-team probes.
Input. Your prompts, models, and application endpoints.
Runs the test? Yes, locally or self-hosted.
Price. Enterprise and on-premises are custom.
Free plan or trial. The Community edition is open source, runs locally or self-hosted, and includes 10,000 red-team probes a month at no charge. Read 15 September 2026.
Main limit. It does not do UI or API regression testing. It sits beside one of the other nine, never instead of it.
How to choose generative AI tools for software testing
Seven questions separate these products faster than any feature list.
Test layer. Unit, API, UI, or LLM output. Nothing here is good at all four, and a tool bought for the wrong layer never recovers.
Input. A spec, a Postman collection, a spreadsheet, source code, a recorded session, or a sentence. Pick the one you can actually supply this week.
Executable output. Does it hand you a script you own, or a test that only exists inside the vendor's platform. This decides how expensive leaving is.
Approval. Can a person review generated tests before they gate a merge. If generated output can block a release unreviewed, you have shifted risk, not removed it.
CI. Does it run on a pull request without a person pressing a button.
Deployment. Vendor cloud, self-hosted, or local. If your test data is regulated, the deployment option is the constraint that decides the shortlist.
Price unit. Credits, agents, covered lines, parallel sessions, or projects. Model your own volume against the unit before comparing headline numbers.
No independent benchmark was run for this page, so treat every speed, scale and quality claim as something to measure yourself. Run a two-week proof of concept on a real repository with real churn, and score it on five things you can count. How many generated tests survived review and landed. How many real defects they caught that your existing suite missed. How many failures were the test's fault rather than the code's. How much time you spent fixing generated tests. What the fortnight actually cost at the vendor's unit. A tool that wins on the demo application and loses on those five numbers is not the tool for you.
Where generated tests fail
Self-healing is the risk people underestimate. A tool that quietly repairs a broken locator can repair its way past a genuine regression, and the suite stays green while the product is wrong. Code Quality makes this warning most directly, and it is the right one to take seriously. Read 15 September 2026. The rule that keeps healing safe is narrow: it may change how a test finds an element, never what the test checks.
Three more failure modes matter when you are buying a generator. Incomplete requirements produce incomplete tests, because the model fills gaps with plausible guesses rather than questions. Tests generated from source code reproduce the implementation's assumptions, so a bug becomes a test that defends it. And volume hides weakness: a hundred generated cases that assert almost nothing look like coverage in a report. AI testing software and QA tools covers the wider reliability picture, including non-deterministic output. All three are caught by the same thing, which is a person reading the test before it can block a merge. That review is the cost nobody puts in the business case.
Frequently Asked Questions
What is a generative AI testing tool?
A tool that uses a generative model to produce a testing artifact: a scenario, a test case, a script, a data set, an assertion, or an evaluation. NIST's definition of generative AI is a model that emulates its input data to generate derived synthetic content, and the testing version narrows that content to something you can run. Tools that only rank, compare, or repair existing tests are AI-assisted, but they are not generating anything.
How is generative AI different from traditional test automation?
Traditional automation is deterministic. The same script, build, and data produce the same verdict every time, and a person writes and maintains the script. Generative AI is probabilistic: it proposes tests, and the same request can produce different output on different days. The workable arrangement keeps the model at authoring and triage, and keeps saved, reviewed code in the execution path, so what gates your merges stays repeatable.
Can generative AI write executable test scripts?
Yes. Diffblue generates Java and Python unit tests and verifies that they compile and pass. Qodex saves a UI run as Playwright you own. testRigor's plain-English tests are themselves executable. What varies is whether you get portable code or a test that only runs inside the vendor's platform, and that distinction matters more a year in than it does during the trial.
Can generative AI replace software testers?
No. It does volume work well: drafting cases, generating unit tests, building data, summarizing a wall of CI failures. It cannot decide which risks matter for this release, notice that something is technically correct but wrong for the user, or own the call to ship with a known defect. The realistic change is what a tester spends the day on, not whether the role exists.
Which generative AI tool is best for test-data generation?
ACCELQ Autopilot is the one on this list that names test data generation as a feature alongside its automation logic, and mabl generates across web, mobile, and API. Whichever you use, the constraints matter more than the volume: generated data has to satisfy your schema, respect real referential integrity, and never be seeded from production records. Our introduction to data-driven testing covers how to structure it.
What should you test in a proof of concept?
Run it on a repository with real churn for two weeks, not on a sample application. Count the generated tests that survived review, the real defects found, the failures caused by the test rather than the code, the hours spent repairing generated tests, and the actual spend at the vendor's unit. A tool that only ever sees a stable interface tells you nothing about what maintenance will cost you.
Shortlist by the job you have
Unit coverage on Java or Python is Diffblue. API and UI scenarios generated from a spec or a sentence and run on every pull request is Qodex. Plain English owned by people who do not write code is testRigor or Momentic. One platform across several layers is mabl, Testsigma, or ACCELQ. Visual regression first is Applitools. A generative feature in your own product is Promptfoo. Pick the layer, then run the fortnight.