AI in Software Testing: What It Does Today
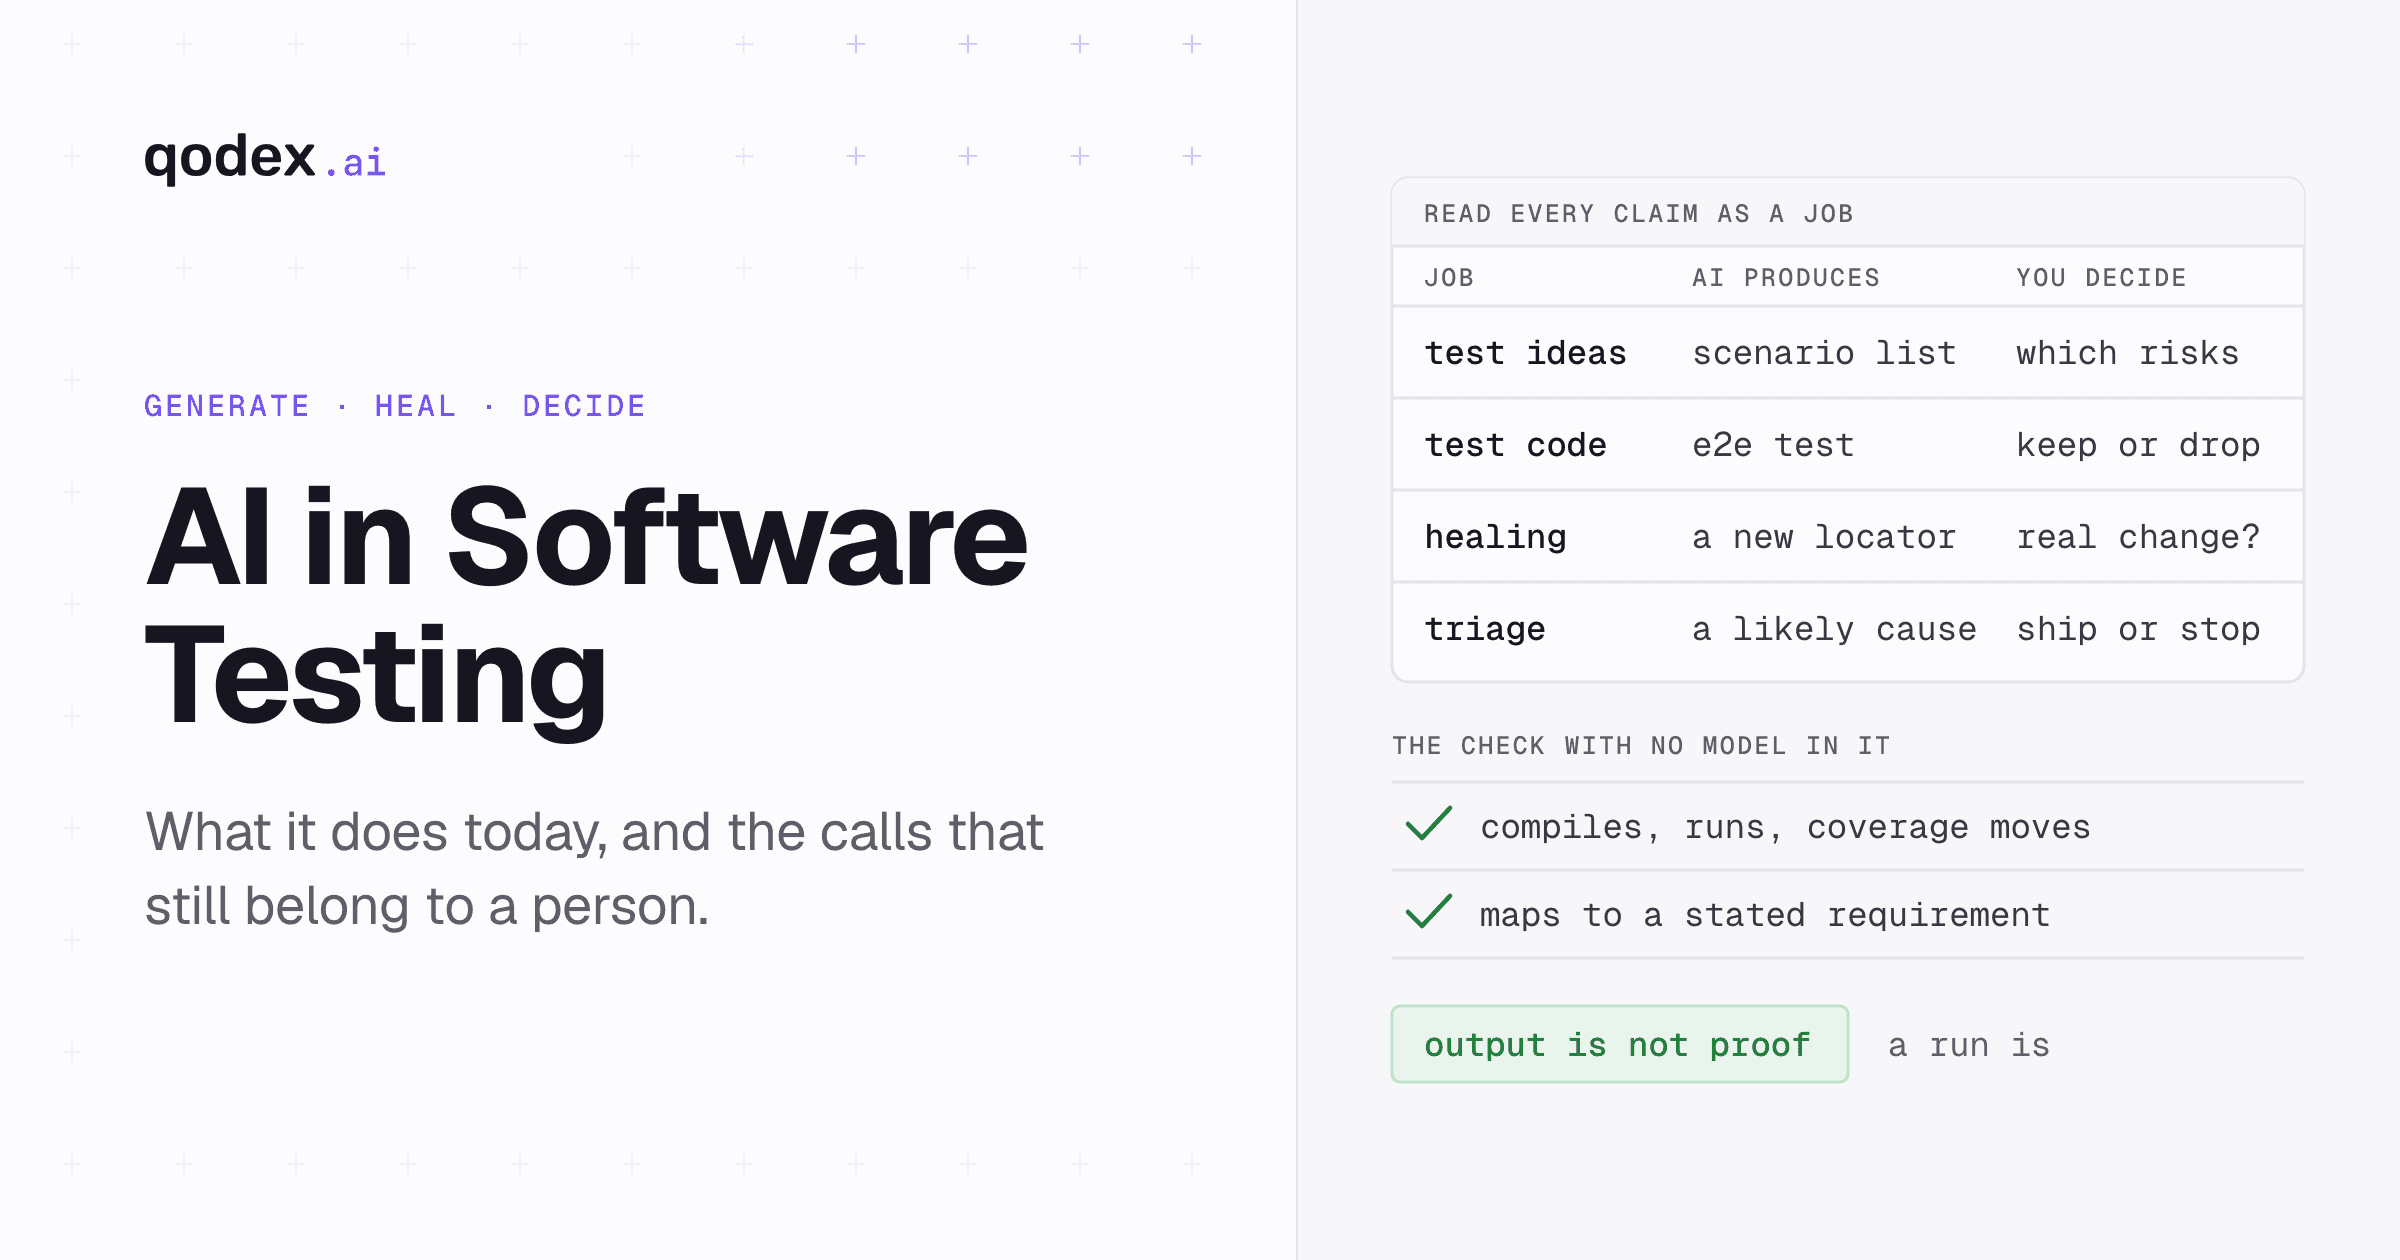
AI in software testing helps teams design test cases, generate data and scripts, choose which tests to run, adapt automation when the interface moves, compare visual results, and investigate failures. It works best as an assistant wrapped around deterministic checks, not as a judge of whether the software is good enough. People still set the risk, read ambiguous behavior, protect sensitive data, and decide whether the evidence supports a release.
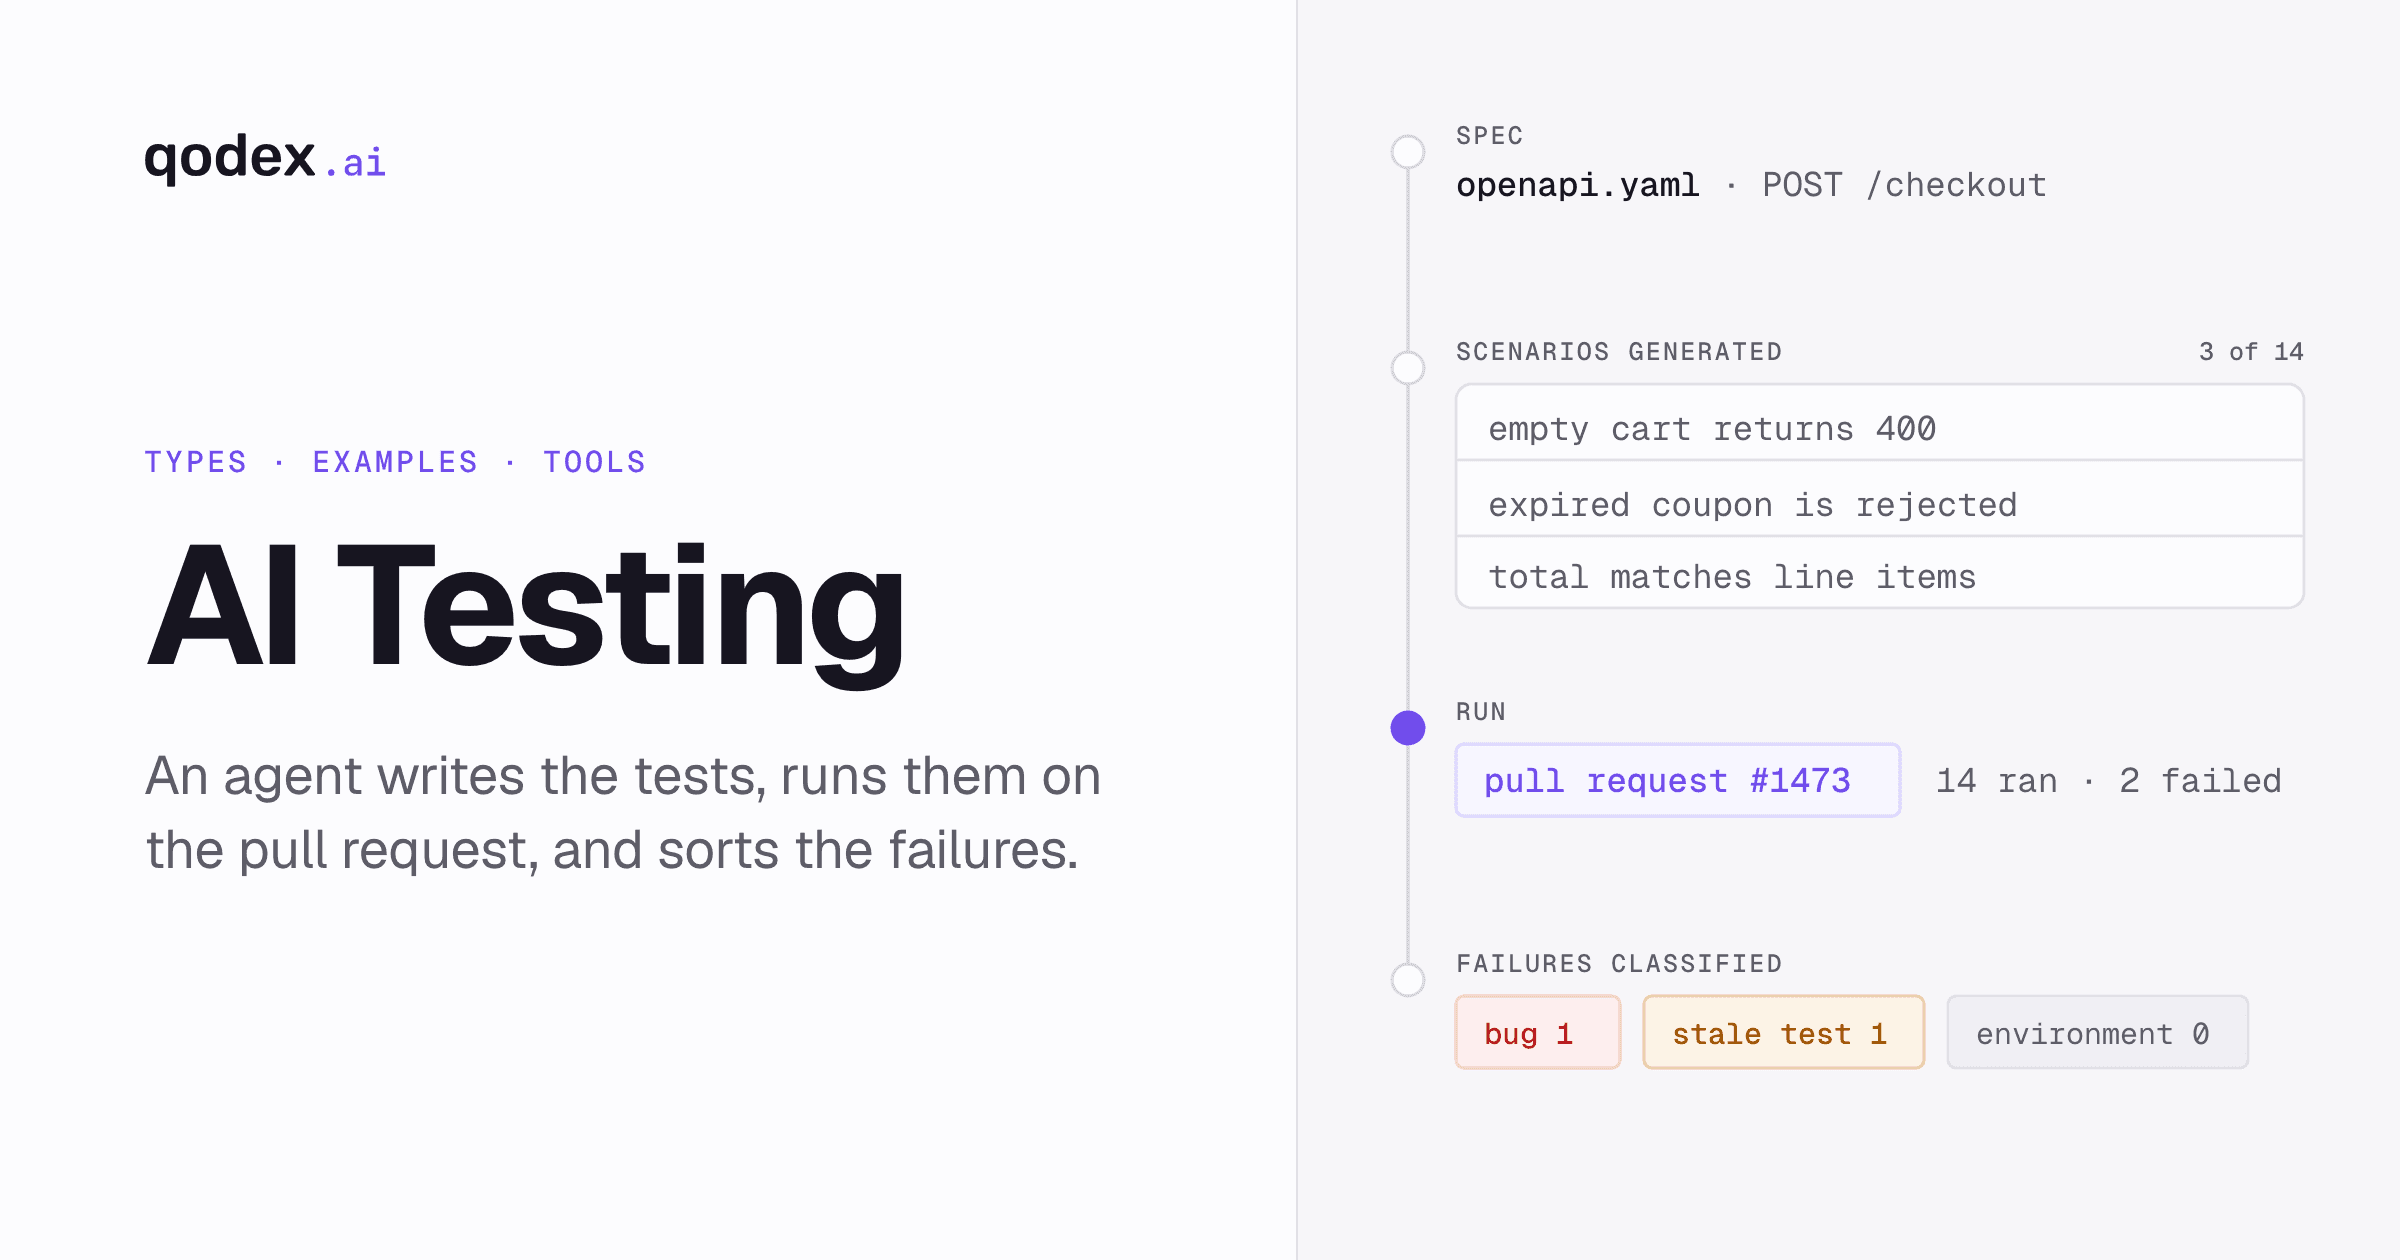
Describe the flow in a sentence. Qodex drives the real app, brings back a screenshot of what broke, and saves the run as Playwright you own.
This page explains what the technology actually does today. If you are shopping, the roundup of best AI QA tools does the product comparison, including no-code platforms such as mabl and its near neighbours. The AI QA guide covers the underlying machine learning, language and vision techniques, and AI regression testing covers what all this means inside a regression suite. This page stays on the job level: what AI does, what checks it, and what a person still decides.
What AI in software testing means
Two different jobs share the name. One is using AI to do testing work. The other is testing a product that has AI inside it. ISTQB separates them, and the split is a useful way to read any vendor page.
Using AI for testing. The CT-GenAI syllabus covers testers applying generative AI across requirements analysis, test design, automation and reporting, and names hallucinations, reasoning errors, bias, data privacy and security, and energy use as the risks to manage. Read 14 September 2026.
Testing AI systems. The CT-AI v2.0 syllabus covers testing AI-based systems, including machine learning systems and large language models, with input data testing, model testing and ML development testing. It deals with the probabilistic behavior, non-determinism, data, models and quality characteristics of the system under test, which is a different set of problems from the one on this page. Read 14 September 2026.
This page is about the first job. Inside it, four different technologies get called AI, and they behave differently.
Generative assistance. A language model drafts plans, cases, scripts, data and summaries. The output is probabilistic, so the same prompt can return something different tomorrow.
Classification and prioritization. A model ranks tests against a change, groups similar failures, and flags patterns that look flaky.
Computer vision. Rendered pages are compared for layout and rendering differences instead of asserting on DOM attributes one at a time.
Runtime agents. A model drives the application, decides the next step, and reacts to what it sees rather than replaying a fixed script.
Ask which of the four a feature uses. The answer predicts how repeatable it is, how you validate it, and what it costs to run.
What AI does across the testing lifecycle
The useful way to read any AI testing claim is as a job with an input, an output, a check that does not involve a model, and a decision that stays with a person. The table below does that for the work AI touches today.
| Testing job | Input AI needs | Output AI produces | Deterministic check | Human decision | Best fit | Main risk |
|---|---|---|---|---|---|---|
| Turn requirements into test ideas | Requirement, user flow, app access | Scenario list with edge cases | Each scenario maps to a stated requirement | Which risks matter for this release | New or poorly documented features | Plausible scenarios that miss the real risk |
| Draft a test plan | Scope, environment, a seed test | Readable plan with steps and data | Plan runs end to end once by hand | Coverage and depth per area | Regression planning for a known app | Coverage that reads complete but is not |
| Generate executable tests | Source code, plan, examples | Unit or end to end test code | Compile, run, coverage delta, assertion review | Whether the test belongs in the suite | Unit tests and happy-path flows | Tests that pass without asserting anything |
| Build test data | Schema, constraints, volume | Synthetic records and fixtures | Schema and constraint validation | What production data may leave the estate | Load data and edge-case records | Real data leaking into a prompt |
| Drive the application at runtime | App access, goal in words | A completed or failed run | Screenshot, network log, exit code | Whether a deviation is a bug | Exploration and first-pass authoring | Slower, less repeatable than a script |
| Repair broken automation | Failing test, page state, history | Proposed locator or step change | Test fails on the old build, passes on the new | Accept, reject, or investigate | Cosmetic and structural UI churn | A repair that silently matches the wrong element |
| Compare visual output | Baseline and current render | Diff regions and a verdict | Baseline approved by a person | Whether the difference is intended | Layout and cross-browser regressions | Noise tuned out until real breaks are missed |
| Select tests for a change | Diff, history, coverage data | Ranked subset to run now | Full suite on a schedule as the backstop | Whether the subset is enough to merge | Large suites and slow pipelines | Missed regression outside the ranked set |
| Triage and summarize failures | Logs, traces, screenshots, history | Grouped failures and a draft cause | The raw failure artifact stays the evidence | The actual root cause and the fix | Noisy CI with repeated failures | A confident summary that is wrong |
Planning sits upstream of all of it, and the mechanics are covered in the guide to test plan document creation. On the API side, generation is the most mature use, worked through in automating API testing with AI in 30 minutes and the wider API testing guide. Selection and triage pay off inside the pipeline, which is where AI regression testing and current CI/CD trends pick up the thread.
Test generation: useful output is not proof
Generation is the one area with published independent evidence, and the evidence is specific rather than sweeping.
Meta ran its TestGen-LLM system against Reels and Stories on Instagram. Of the test cases it produced, 75% built correctly, 57% passed reliably, and 25% increased coverage. Those are evaluation results from one deployment, not a success rate you should expect on your own code. Read 14 September 2026.
CoverUp, a Python test generator that feeds coverage gaps back into the prompt, reached a per-module median line and branch coverage of 80% against CodaMosa's 47%, and 89% overall against MuTAP's 77%. Again, these are benchmark numbers on open source modules. Read 14 September 2026.
Read both results the same way. A model can write a large volume of test code quickly, and a meaningful share of it is wrong, weak, or redundant. That is fine, because the filters are cheap and mechanical.
It compiles. Anything that does not build is discarded without a human looking at it.
It runs and passes repeatedly. Run each candidate several times. Drop anything that flickers.
It adds coverage. Keep the candidate only if it covers lines or branches the suite was missing.
It asserts something. A test that exercises code without checking the result is a false signal. Assertion design is its own skill, covered in the guide to Playwright assertions.
A person approves it. Someone who knows the feature reads the test before it can gate a merge.
Generation also starts earlier than the code. Playwright's planner agent explores a running app and writes a Markdown plan you can read before anything is generated from it, and it needs a clear request and a seed test to work from. That gives a person a review point before test generation begins. Source: Playwright Test Agents, read 14 September 2026.
Tooling increasingly builds the gates in. GitHub documents unit-test generation as a Copilot workflow, and Playwright's generator agent verifies selectors and assertions live against the running app while it writes the test. Both read 14 September 2026. Neither removes the review step.
Self-healing and agentic execution
Two capabilities get confused because both involve a model at run time.
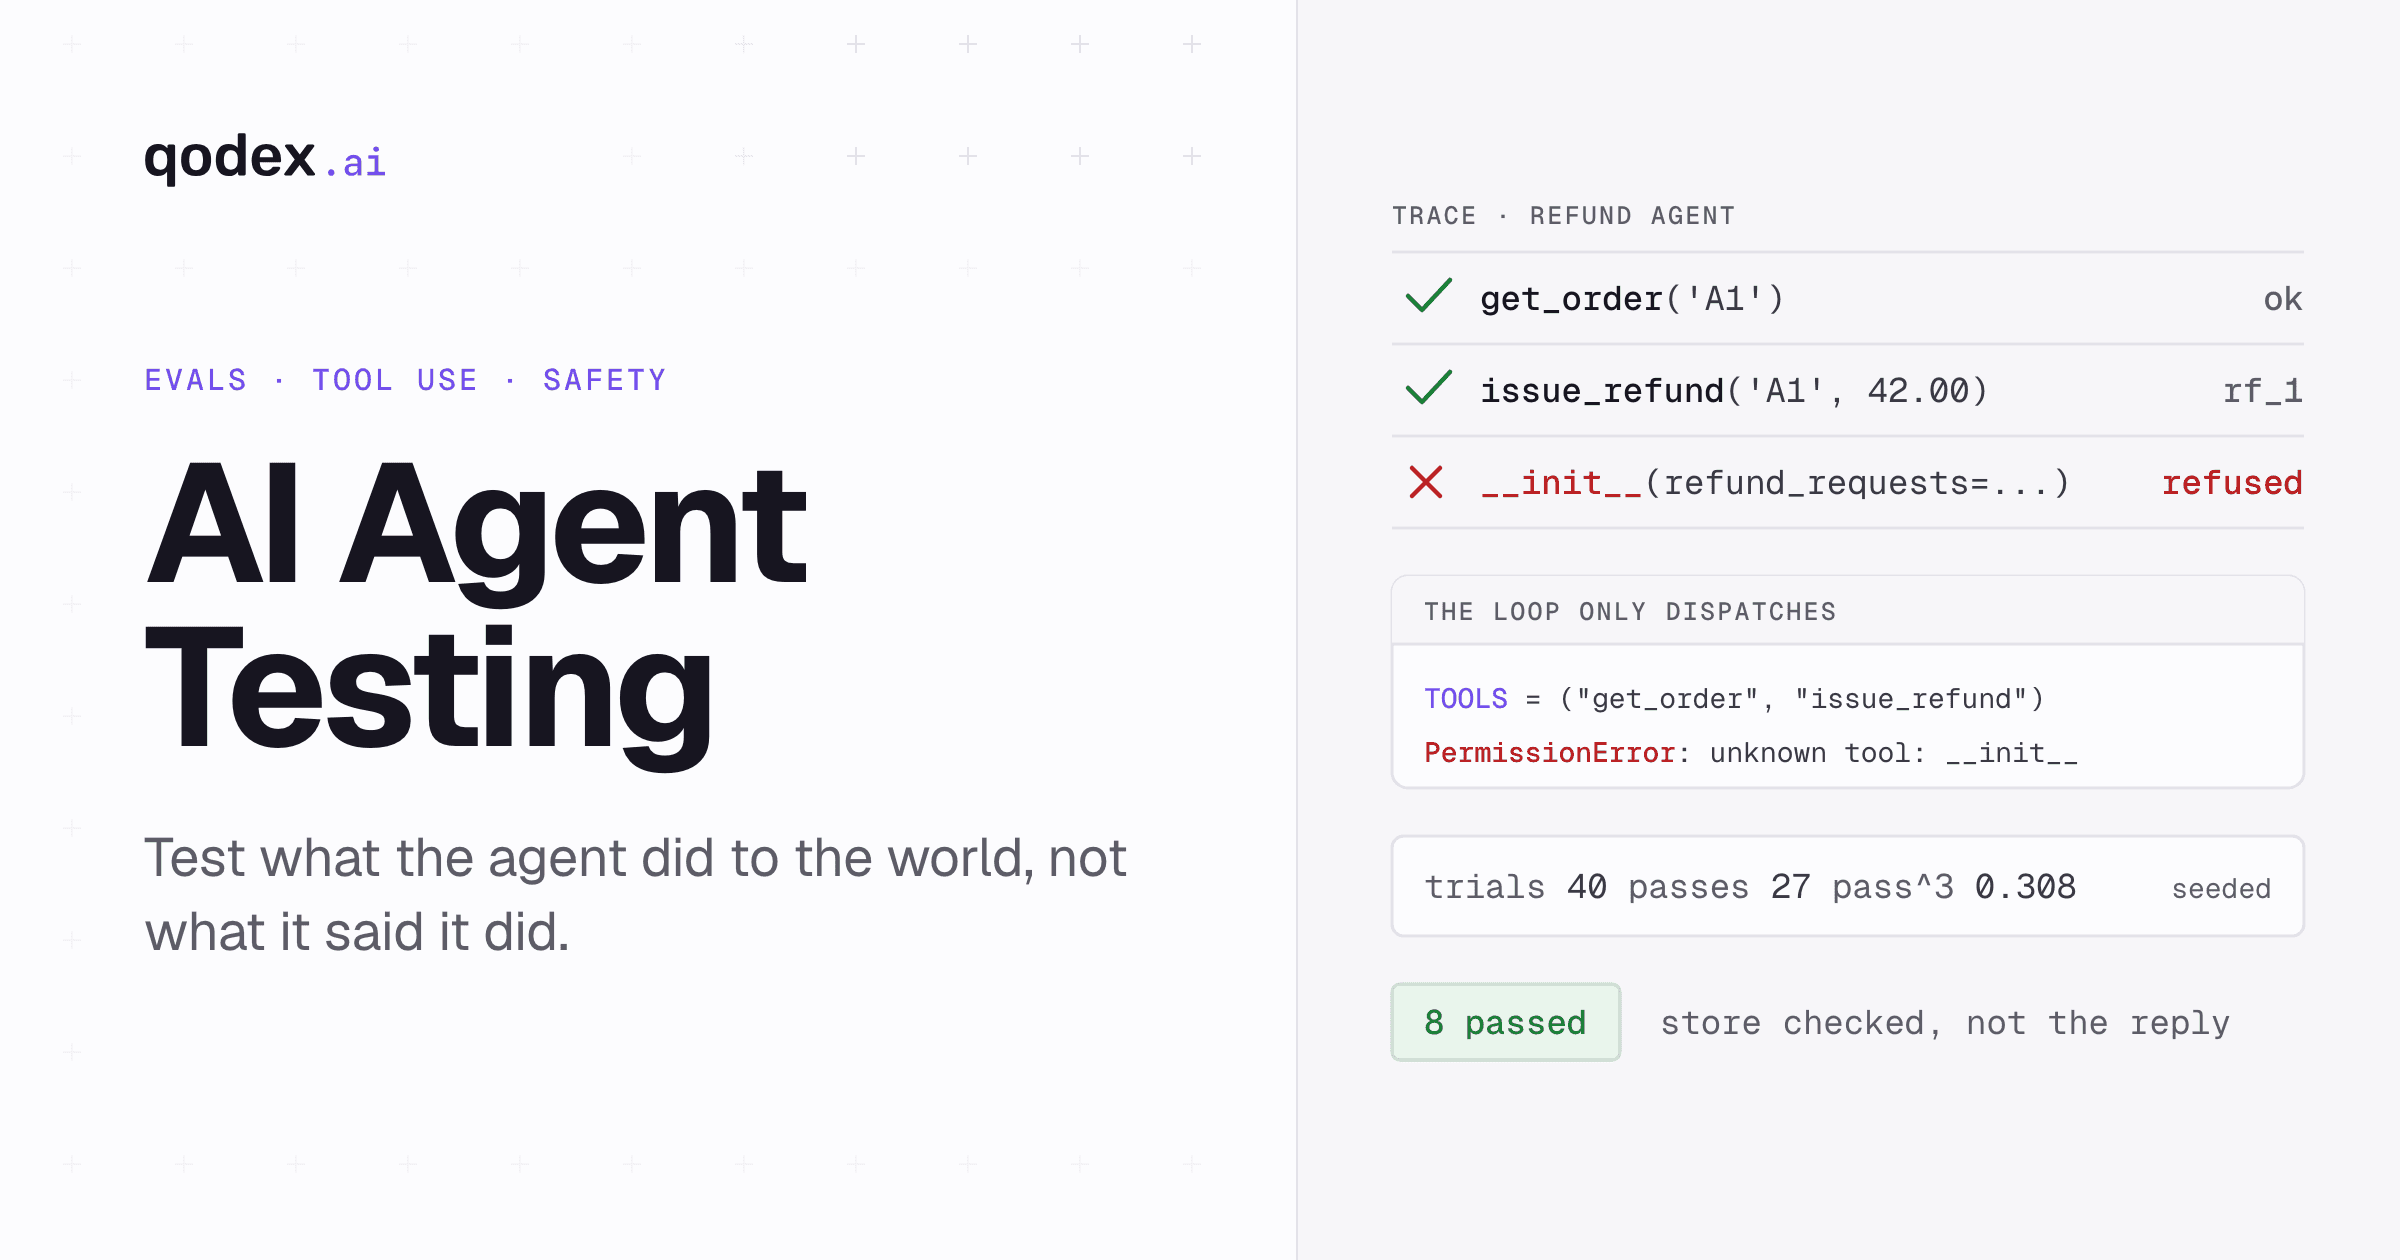
Building an AI feature creates a second QA problem: test the AI agent across its tools, multi-step decisions, guardrails, and repeated runs.
Self-healing repairs automation that broke because the interface moved. When a button changes its attributes, a model uses the surrounding attributes, the visible text and the visual context to propose a replacement locator or step. mabl describes an agent that updates tests autonomously and asks a person for the reasoning behind an action when it needs that context. Its claim of eliminating up to 95% of test maintenance is the vendor's own figure, published without a method. Applitools says its locators find a changed element using visual and semantic clues, and that its Visual AI catches rendering and layout regressions. Also a vendor claim. Both read 14 September 2026.
The honest framing is that self-healing changes how a test finds things, and it must never change what a test checks. A repaired locator that matches a similar but different element turns a green build into a lie. Treat every repair as a pull request: it is proposed, reviewed, and reversible, and the test has to fail on the broken build before the repair counts. The vendor-by-vendor mechanics, including what each one exposes for review and rollback, are worked through in AI regression testing.
Agentic execution is different. Here the model drives the app toward a goal and decides each next step. Playwright ships planner, generator and healer agents, added in version 1.56, with 1.63 current in the release notes. The docs note that agent definitions should be regenerated whenever Playwright is updated. Read 14 September 2026.
Agents are strong where the path is unknown: exploring a new feature, reproducing a vague bug report, or writing the first version of a flow. They are a poor fit for regression, where you want the same steps, the same data and the same verdict on every run. TestGuild, reviewing runtime agents, points out that agentic execution can be slower and less predictable than a script. The practical design is to use the model once, at authoring and at triage, then save the approved run as code and replay that code with no model in the loop. Cost, speed and repeatability all improve at the same time.
Where AI fails, and what humans still own
The failures are consistent across teams, and none of them are fixed by a better prompt.
Missing business context. A model reads the code and the screen. It does not know that a refund over a certain amount needs a second approver, or which customer segment cannot tolerate a slow checkout. It generates what looks testable, not what is risky.
False confidence. Generated tests and generated summaries read as authoritative. A wrong root cause stated clearly costs more than no root cause, because it sends someone down the wrong path with conviction.
Weak assertions. The easiest test to generate is one that navigates, waits, and checks that the page loaded. It passes forever and catches nothing.
Privacy and data handling. Prompts that carry production records, tokens or proprietary source leave your estate. ISTQB lists data privacy and security as a core risk of generative AI in testing. Decide what may be sent before anyone starts, not after.
Bias in prioritization. A selection model trained on past failures keeps testing what has broken before. New code with no history gets less attention, which is precisely where regressions hide.
Non-determinism. The same request can produce different output on different days. That is acceptable while authoring and unacceptable in a gate, which is why the model belongs outside the replay loop.
Tests rewritten to pass. An agent asked to make the suite green can weaken an assertion, widen a wait, or skip a case. Protect the assertion in review and watch for suspiciously fast fixes.
The release decision. Whether a known defect is shippable is a judgement about users, contracts and timing. No model holds the information required to make it.
Qt's write-up on AI in testing puts the working relationship well: "The future of software testing is not AI or human, just like it was never manual or automated." Read 14 September 2026. The practical version of that is a division of labor. AI does volume work with a cheap mechanical check attached. People own risk, ambiguity, data boundaries and the decision to ship.
How to adopt AI in QA without losing control
Teams that get value from this start narrow and measure. Teams that do not start by buying a platform and hoping.
Pick one pain. Flaky maintenance, slow pipelines, thin unit coverage, or noisy triage. Pick the one that is costing you time this month. TestGuild's advice to readers choosing a tool is to "start with the pain, not the hype", and it applies before any tool is involved. Read 14 September 2026.
Baseline it first. Write down the current number: hours a week on test maintenance, minutes of pipeline wall time, percentage of failures that are real. Without a baseline you cannot tell a benefit from a story.
Pilot on representative work. Use a real repository with real churn, not a sample app. A tool that only ever sees a stable interface tells you nothing about maintenance.
Keep raw evidence. The failing request, the response, the screenshot, the trace. A model-written summary is a starting point for investigation and never the record of what happened.
Require review where it gates. Anything that can block a merge is read by a person first. Anything advisory can flow.
Draw the determinism line. Model at authoring and triage. Saved code at execution. Write that boundary down so it survives the next tool.
Then measure the things that move if this is working.
Accepted tests. Of the tests the model proposed, how many survived review and landed in the suite.
Valid defects. How many real bugs came from AI-assisted work, separated from noise.
Maintenance time. Hours a week spent fixing tests, against the baseline you wrote down.
Flake rate. Share of runs that fail without a code change. Agentic execution tends to push this up.
Escaped defects. Bugs that reached production. If selection is trimming the suite, this is the number that tells you when it trimmed too far.
Vendor claims sit outside all of this. CloudBees says Smart Tests prioritizes tests likely to catch relevant failures, classifies failures, and delivers developer feedback up to 80% faster. Read 14 September 2026. That is the vendor's own figure, not a benchmark. Your pilot numbers are the ones that decide.
Frequently Asked Questions
What is AI in software testing?
Using AI to support testing work: drafting scenarios, writing test code, building data, driving the app, repairing broken automation, comparing visuals, ranking tests against a change, and grouping failures. ISTQB's CT-GenAI syllabus covers this ground. It is separate from testing a product that has AI inside it, which is what CT-AI v2.0 covers.
How is AI used by QA testers today?
Mostly for volume work with a cheap check attached. Testers use it to draft test cases from a requirement, generate unit and end to end tests, and create synthetic data. It also proposes locator repairs when the UI changes and summarizes a wall of CI failures into a shortlist. The tester decides what is risky, reviews what the model produced, and owns the release call.
What is the difference between AI testing and test automation?
Automation is deterministic by design. Given the same build, the same data and the same environment, a script runs the same steps and produces the same verdict, and a person maintains it. Change any of those three and the result can change, which is why controlling those inputs matters. AI is probabilistic in a different way: it proposes, ranks, repairs and explains, and the output can differ between runs on identical inputs. In a working setup AI sits around the automation, not inside the execution path, so the gate stays as repeatable as your inputs are. For how AI test automation works in practice, and the metrics and ROI to hold it to, read our guide to AI test automation.
Can AI generate reliable test cases?
It generates useful candidates that need filtering. In Meta's TestGen-LLM evaluation, 75% of generated cases built, 57% passed reliably, and 25% increased coverage. Run the same gates on your own output: it compiles, it passes repeatedly, it raises coverage, it asserts something real, and a person who knows the feature approves it before it can block a merge.
What are self-healing tests?
Tests that propose their own repair when the interface changes. A model reads attributes, text and visual context, works out which element the old step meant, and suggests a new locator or step. mabl and Applitools both ship a version of this. The rule that keeps it safe is that healing may change how a test finds an element and never what the test checks.
Can AI run exploratory tests?
Partly. An agent can wander a new feature, try inputs a script would not, and surface states nobody wrote down, which is genuinely useful on unfamiliar ground. It cannot form a hypothesis about what would hurt this business, and it does not notice that something is technically correct but wrong for the user. Treat agent runs as raw material for a tester, not a replacement.
Will AI replace QA testers?
No, and the work that disappears is not the work that matters. Drafting boilerplate cases, fixing locators, and reading logs shrinks. Deciding what is risky, reading ambiguous behavior, arguing about whether a defect is shippable, and designing the assertion that actually catches the bug does not. Testers who can direct and audit model output end up doing more of the interesting half.
What are the risks of AI in software testing?
Tests that pass without checking anything. Repairs that match the wrong element and turn a green build into a lie. Confident but wrong failure explanations. Production data and source code sent into a prompt. Prioritization that keeps testing what already broke and ignores new code. Output that varies between runs. The controls differ by risk. Weak assertions, bad repairs and drifting output are caught by mechanical gates: assertion review, a coverage delta, a test that must fail on the broken build, a full suite on a schedule behind any ranked subset. Privacy, bias and the release decision are not. Those need a written rule about what may be sent, a person watching what the ranking stops testing, and a human owner for the call to ship.
Is AI testing a tool, a service, or a capability?
A capability that you can buy as either. Platforms sell it as features inside a product. Agencies sell it as an AI-assisted testing service. Open source gives it to you directly, as with Playwright's planner, generator and healer agents. What you are really buying is where the model sits in your workflow and who reviews its output, so judge any of the three on that.
Is there a recognized 30% rule for AI in testing?
No. The phrase turns up in search suggestions, but no testing standard, syllabus or credible body defines a 30% rule, and the numbers people attach to it vary with whoever is quoting it. Ignore it. Decide how much of your testing work AI touches by measuring accepted tests, valid defects, maintenance hours and escaped defects on your own suite.