Regression Testing: What It Is and How to Automate It
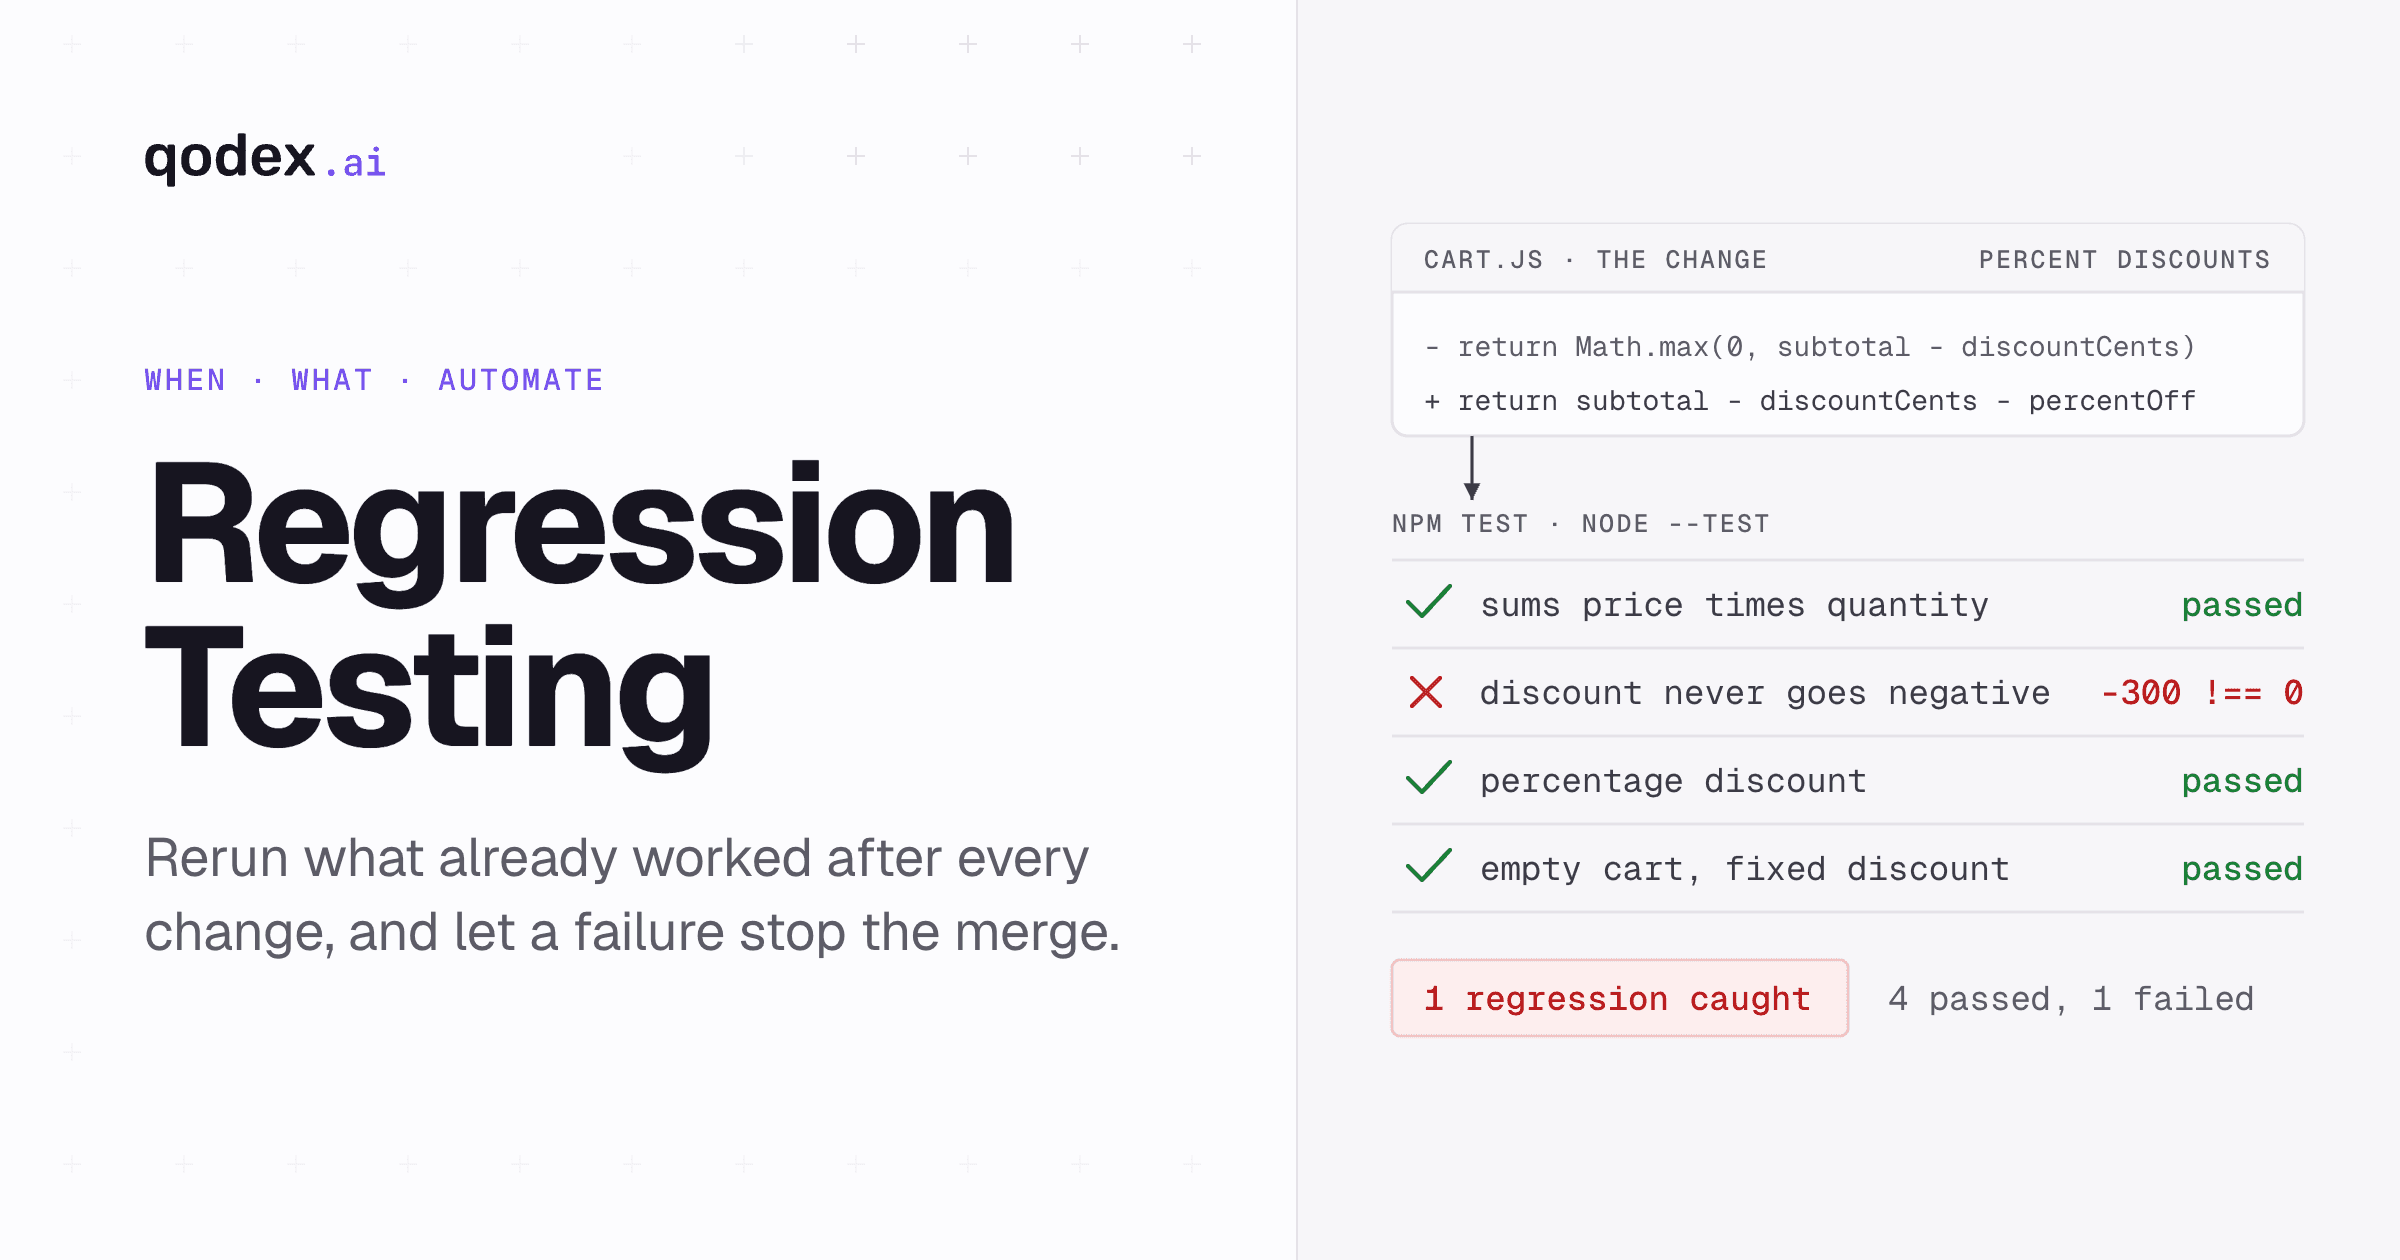
Regression testing is rerunning tests that already passed after a change to the code, its dependencies, configuration or environment. It catches behavior that worked before and stopped working. It is a reason to run a test, not a kind of test: unit, API and browser tests can all be regression tests. Run the tests a change can reach on each pull request, and the full suite on a schedule.
Qodex UI testing writes these scenarios for you, runs them on every pull request, and saves them as standard Playwright code you own.
Regression testing at a glance.
| Question | Short answer |
|---|---|
| What it checks | Behavior that worked before a change and was not meant to change |
| What triggers it | A code change, a bug fix, a dependency update, a configuration change, an environment change |
| What runs | The tests the change can reach plus a small critical set on the pull request; the full suite after merge or nightly |
| Who acts on a failure | The author of the change, before merge; the suite owner when the failure is in the test itself |
| What it cannot catch | A behavior nobody wrote a test for, and whether the new feature is right |
What is regression testing?
ISTQB, which publishes a standard software testing glossary, defines regression testing as "A type of change-related testing to detect whether defects have been introduced or uncovered in unchanged areas of the software." Two parts of that sentence decide how you run it.
Change-related. Regression testing is not a test level such as unit or system testing, and it is not a phase at the end of a release. A run counts as a regression run because something changed. The same test file can prove a new feature on the day it is written, and guard that feature in every run after.
Unchanged areas. The target is behavior nobody meant to touch. A regression is the defect itself: a feature that worked in the last release and fails in this one. Say a developer changes a shared currency formatter to support yen. The invoice screen, which nobody edited, now prints totals without decimals. A regression test on the invoice screen catches that before a customer does.
"Uncovered" matters too. A change can expose a defect that was already there, such as an old race condition that a faster query now triggers. The test that fails did not change, and the code it tests did not change, but the result did.
Regression testing is one of the practices in our software testing guide, which maps where it sits among the other test types and levels.
When to run regression testing
Run it after any change that can reach behavior that already works. The change does not have to be in your own code.
| Trigger | Example | What to rerun | Where it runs |
|---|---|---|---|
| New feature | A percentage discount added to checkout | Tests for checkout, pricing and anything that reads the total | Pull request |
| Bug fix | A fix to how refunds round | The refund tests plus the tests that share the rounding helper | Pull request |
| Dependency update | A new major version of the date library | Tests for every screen and job that formats or parses dates | Pull request, then nightly |
| Configuration change | A timeout cut from 30 to 10 seconds | The flows that call the slow service | Before the change ships |
| Environment change | A runtime upgrade, a new database version | The full suite | Nightly or before release |
The table numbers are examples, not thresholds. The rule behind them is impact: what can this change reach? ISTQB calls that question impact analysis, "The identification of all work products affected by a change, including an estimate of the resources needed to accomplish the change."
Cadence follows from cost. A pull request run has to finish while the author is still waiting, so it runs a selected set. A run after merge, a nightly run and a run before release can take longer, so they run more. The full nightly run also checks the selection: a failure there that the pull request run missed means the selector skipped a test it should have chosen.
Types of regression testing
Yoo and Harman's survey, Regression testing minimization, selection and prioritization: a survey (Software Testing, Verification and Reliability, 2012), organizes the research around three techniques. Retest all is the baseline they are measured against.
Retest all. Run the whole suite after each change. Nothing is skipped, so nothing is missed by a bad selection. It is the right default for a small suite and the wrong one when a run takes an hour.
Regression test selection. Run only the tests whose code paths the change touches. Path filters, tags and coverage maps from earlier runs do the choosing. It keeps pull request runs fast and depends on the map being current.
Test case prioritization. Run everything, in an order that finds failures early: tests for recently changed code, for areas with past failures, for the paths that carry money or logins. ISTQB's risk-based testing entry describes the same idea for test effort in general.
Test suite minimization. Remove tests that cover nothing another test does not already cover. It shrinks the suite for good, so it needs care: a test that looks redundant by line coverage can still be the only one that checks a specific value.
You will also meet "partial" and "complete" regression testing. Partial means a selected set, complete means retest all. They are the same two ideas under other names.
Regression testing vs retesting, smoke, sanity and functional testing
These terms overlap because they describe different things: why a test runs, how deep it goes, and when. One test can be several of them on different days.
| Term | The question it answers | When it runs | Full comparison |
|---|---|---|---|
| Retesting | Is this specific bug fixed? | After the fix, on the failed case only | Retesting vs regression testing |
| Smoke testing | Does the build start and do its main paths respond? | On every new build, before deeper testing | Smoke testing guide |
| Sanity testing | Does the changed area work well enough to test further? | After a small change, before a full run | Sanity vs regression testing |
| Functional testing | Does the feature do what its requirement says? | While the feature is built | Functional vs regression testing |
| Regression testing | Did the change break something that worked? | After any change that can reach existing behavior | This page |
ISTQB's name for retesting is confirmation testing: "A type of change-related testing performed after fixing a defect to confirm that a failure caused by that defect does not reoccur." A fix needs both runs. The confirmation test shows the bug is gone, and the regression run shows the fix broke nothing the suite checks.
How to build a regression test suite
A regression test suite is the set of tests you rerun after a change. ISTQB defines a test suite as "A set of test scripts or test procedures to be executed in a specific test run." Building one comes down to what to put in and how to label it.
1. Start from what would hurt
List the flows where a break costs money, data or trust: sign-up and login, checkout and refunds, permissions between accounts, data exports. Each one gets at least one end-to-end or API test before anything else goes in.
2. Turn every fixed bug into a test
When a bug is fixed, the case that reproduced it becomes a permanent test. That test failed once in the real world, so it guards a path you already know can break, and its reason to exist is already written in the bug report.
3. Cover the code that changes most
Your version control history shows which files change most often. Areas with many changes and many past bugs earn more tests than stable code nobody touches.
4. Label every test by area and priority
Tags or name prefixes let you select later without rewriting anything. Use one label for the area, such as checkout, and one for priority, such as critical. The worked example below selects its critical tests by name.
5. Record why each test exists
A test with no recorded reason is hard to delete and hard to fix. Keep a short record per test, in the test name, a comment or a spreadsheet. A regression testing template with six fields is enough:
| ID | Area | What it protects | Priority | Origin | Runs on |
|---|---|---|---|---|---|
| REG-014 | Checkout | A discount never makes the total negative | Critical | Bug 482, fixed in v3.2 | Pull request |
| REG-015 | Checkout | Percentage discounts round to the nearest cent | High | Requirement PRC-9 | Pull request |
| REG-031 | Accounts | A user cannot read another account's invoices | Critical | Security review | Pull request |
| REG-052 | Reports | The monthly export opens in a spreadsheet | Medium | Customer ticket | Nightly |
The rows are examples. "Origin" is the field that pays off: when a test fails, it tells the reader what the test was protecting and who asked for it.
There is no correct number of test cases for a regression suite. Size it by time instead: the pull request set has to finish while the author waits, and the full suite has to finish inside its nightly window. When a run outgrows its window, select or prioritize before you delete.
How to maintain a regression test suite
A suite that only grows gets slower, and a slow suite tempts people to skip it. Four habits keep it worth running.
Classify every failure. A red test is a product bug, a test bug, or an environment problem. Write down which, because the fix and the owner differ for each.
Quarantine flaky tests, with a deadline. A test that passes and fails on the same code teaches people to ignore red. Move it out of the blocking run, record why, and fix or delete it by a set date.
Delete tests for removed features. When a feature goes, its tests go in the same pull request.
Review the suite on a schedule. Once a quarter, read the slowest tests, the tests that never failed, and the failures the pull request run missed. Each one is a candidate to speed up, merge or select better.
What to do when a regression test fails
A red regression test is a question, not a verdict. Work through four answers in order before anyone edits code.
Does it fail again on the same commit? Rerun it once. A test that passes on the rerun with no change is flaky. Quarantine it with a ticket and find the cause, because an intermittent failure can be a real product bug, such as a race condition.
Did the change mean to alter this behavior? If the product owner agrees the old behavior should go, update the test in the same pull request, so the reviewer sees both.
Is the test itself wrong? A hard-coded date, shared test data, or an assertion on text that was never part of the requirement. Fix the test, and record that it was a test bug.
Is it the environment? An expired certificate, a seed script that did not run, a service that was down. Fix the environment, not the test.
If it fails again, the change did not mean it, and neither the test nor the environment is at fault, it is a regression in the product. The change that caused it is fixed or reverted before merge.
How to automate regression testing
Manual regression testing means a person repeating the same checks before each release. The checklist grows with each feature you ship, and each pass costs the same hours again. Automated regression testing runs the same checks from code, on a trigger, the same way each time.
Automate in tiers, so each run stays inside the time someone can wait for it:
On the pull request. The tests the change can reach, plus the critical set. This run blocks the merge when it fails.
After merge. The full stable suite against the main branch. A failure here means the selection missed something, or two changes broke each other.
Nightly and before release. Everything, including slow browser tests, quarantined tests reported separately, and tests against a production-like environment.
Keep manual testing for what scripts are bad at: exploratory sessions on a new feature, and checks that need human judgment, such as whether a layout looks right. Once a manual check finds a bug, the reproducing case becomes an automated test.
If your pull requests come from AI coding agents, the same tiers apply with more volume. Our guide to AI regression testing covers selection and replay for that case.
Worked example: a regression caught by the suite
This example uses the test runner built into Node.js, so it needs no install. The Node.js documentation lists "v20.0.0: The test runner is now stable." The run below is from Node.js v26.10.0 on 4 October 2026, in an empty folder with these three files.
package.json:
{
  "name": "checkout-regression-demo",
  "private": true,
  "type": "module",
  "scripts": {
    "test": "node --test --test-reporter=spec",
    "test:critical": "node --test --test-reporter=spec --test-name-pattern=critical"
  }
}cart.js, the code under test:
export function orderTotal(items, discountCents = 0) {
  const subtotal = items.reduce((sum, item) => sum + item.priceCents * item.qty, 0);
  return Math.max(0, subtotal - discountCents);
}cart.test.js, the regression suite. Two tests carry the critical: prefix:
import { test } from 'node:test';
import assert from 'node:assert/strict';
import { orderTotal } from './cart.js';

test('critical: sums price times quantity', () => {
  assert.equal(orderTotal([{ priceCents: 1250, qty: 2 }, { priceCents: 499, qty: 1 }]), 2999);
});

test('critical: a discount larger than the order never makes the total negative', () => {
  assert.equal(orderTotal([{ priceCents: 500, qty: 1 }], 800), 0);
});

test('an empty cart costs nothing', () => {
  assert.equal(orderTotal([]), 0);
});

test('a fixed discount comes off the subtotal', () => {
  assert.equal(orderTotal([{ priceCents: 1000, qty: 3 }], 500), 2500);
});
Run the suite with npm test. All four pass:
✔ critical: sums price times quantity (0.2865ms)
✔ critical: a discount larger than the order never makes the total negative (0.047ms)
✔ an empty cart costs nothing (0.0335ms)
✔ a fixed discount comes off the subtotal (0.45175ms)
ℹ tests 4
ℹ pass 4
ℹ fail 0
The pull request tier runs only the critical tests with npm run test:critical. Node.js treats the name pattern as a regular expression and omits tests that do not match from the output:
✔ critical: sums price times quantity (0.279333ms)
✔ critical: a discount larger than the order never makes the total negative (0.05225ms)
ℹ tests 2
ℹ pass 2
ℹ fail 0
Now a feature arrives: percentage discounts. The developer rewrites cart.js and adds a test for the new behavior. The floor at zero falls out of the rewrite:
export function orderTotal(items, discountCents = 0, discountPercent = 0) {
  const subtotal = items.reduce((sum, item) => sum + item.priceCents * item.qty, 0);
  const percentOff = Math.round((subtotal * discountPercent) / 100);
  return subtotal - discountCents - percentOff;
}
The new test, added at the end of cart.test.js:
test('a percentage discount comes off the subtotal', () => {
  assert.equal(orderTotal([{ priceCents: 2000, qty: 1 }], 0, 10), 1800);
});
The new feature's own test passes. The old discount test, which nobody edited, fails. That failure is the regression test doing its job:
✔ critical: sums price times quantity (0.2725ms)
✖ critical: a discount larger than the order never makes the total negative (0.314042ms)
✔ an empty cart costs nothing (0.034791ms)
✔ a fixed discount comes off the subtotal (0.074458ms)
✔ a percentage discount comes off the subtotal (0.051209ms)
ℹ tests 5
ℹ pass 4
ℹ fail 1

✖ failing tests:

test at cart.test.js:9:1
✖ critical: a discount larger than the order never makes the total negative (0.314042ms)
  AssertionError [ERR_ASSERTION]: Expected values to be strictly equal:

  -300 !== 0
A customer with an 800 cent coupon on a 500 cent order would have been owed money. The fix puts the floor back around the whole expression:
export function orderTotal(items, discountCents = 0, discountPercent = 0) {
  const subtotal = items.reduce((sum, item) => sum + item.priceCents * item.qty, 0);
  const percentOff = Math.round((subtotal * discountPercent) / 100);
  return Math.max(0, subtotal - discountCents - percentOff);
}
The suite passes again, now with five tests, and the percentage test joins the regression suite for every change after this one:
✔ critical: sums price times quantity (0.263584ms)
✔ critical: a discount larger than the order never makes the total negative (0.040833ms)
✔ an empty cart costs nothing (0.031458ms)
✔ a fixed discount comes off the subtotal (0.287792ms)
✔ a percentage discount comes off the subtotal (0.068ms)
ℹ tests 5
ℹ pass 5
ℹ fail 0
The output blocks keep the test lines and three of the summary lines. The full logs also print the npm script header, counts for suites, cancelled, skipped and todo, all 0, a total duration, and a stack trace under the failure.
Regression testing tools
Any test framework can run a regression suite. Choose by the layer you test and the language your team writes.
Descriptions were read on each project's own page on 4 October 2026.
The framework matters less than the selection and the tiers around it. A tool that runs fast tests on each pull request and the full suite nightly beats a better tool that runs once before release.
Conclusion
Regression testing answers one question after every change: does what worked still work? Build the suite from the flows that would hurt and from every bug you fix. Label tests so you can select them, run the reachable set on each pull request and the full suite on a schedule. Treat a red test as information about the change, not as noise.
Frequently Asked Questions
What is meant by regression testing?
Regression testing means rerunning tests that passed before, after a change, to check that existing behavior still works. ISTQB defines it as change-related testing that detects defects introduced or uncovered in unchanged areas of the software.
What is regression used to test?
It tests behavior that was not meant to change: features that already shipped, shared code a change touches indirectly, and bugs that were fixed before. Any change can trigger it, including code, dependency updates, configuration and the runtime environment.
What is an example of regression testing?
A team adds percentage discounts to checkout. An older test, which checks that a coupon never makes a total negative, fails after the change with -300 instead of 0. Nobody edited that test. The failure shows the rewrite dropped an existing rule. The worked example above runs exactly that.
What is regression testing vs UAT?
ISTQB defines user acceptance testing (UAT) as "A type of acceptance testing performed to determine if intended users accept the system." It asks whether the system is right for its users. Regression testing asks whether a change broke what already worked, and it runs after each change. A UAT round can include regression checks, but the questions differ.
Is regression testing the same as retesting?
No. Retesting, which ISTQB calls confirmation testing, reruns the case that failed to confirm a fix works. Regression testing runs other tests, over areas the fix could have disturbed. A fix needs both. See retesting vs regression testing.
Can regression testing be automated?
Yes, and it should be wherever a check repeats. Automated regression tests run from code on each pull request and on a schedule. Keep manual testing for exploration and for judgment calls, then automate each bug it finds.
How often should you run regression tests?
Run the tests a change can reach, plus a small critical set, on each pull request. Run the full stable suite after merge or nightly, and before a release. Compare the full run with the pull request run to check that selection works.
What is a regression test suite?
A regression test suite is the set of tests you rerun after changes. It holds tests for critical flows, tests written from fixed bugs, and tests for code that changes often, each labeled by area and priority so a run can select them.